 Universal Dependencies
 (UD) is a framework for consistent annotation of grammar (parts of speech, morphological features, and syntactic dependencies) across different human languages. UD is an open community effort with over 600 contributors producing over 200 treebanks in over 150 languages. If you are new to UD, you should start by reading the first part of the Short Introduction and then browsing the annotation guidelines.
💡 Understanding UD |
🔍 Using UD |
🔨 Contributing to UD |
|---|---|---|
| Short introduction to UD (history) | Query UD treebanks online | How to contribute to UD |
| Annotation guidelines (changes) UPOS tags ▪ feats ▪ deprels ▪ CoNLL-U format |
Download UD treebanks: all releases ☞ Release 2.19 (November 15, 2026) |
UD mailing list |
| Guidelines issue tracker | ||
| Tutorials and events | Tools for working with UD | |
🚀 Projects related to UD | ||
| SUD: Surface Syntactic Universal Dependencies ▪ Deep Universal Dependencies ▪ Universal PropBank ▪ CorefUD: Coreference in Universal Dependencies ▪ UNER: Universal Named Entity Recognition ▪ UMR: Uniform Meaning Representation ▪ UniMorph ▪ UDMorph ▪ UDer: Universal Derivations ▪ PARSEME: Multiword expressions ▪ UniDive COST Action ▪ UCxn: Universal Constructions ▪ UD on Hugging Face | ||
📖 Overview Publications
- Linguistic framework
- Marie-Catherine de Marneffe, Christopher Manning, Joakim Nivre, and Daniel Zeman (2021). Universal Dependencies. Computational Linguistics 47(2): 255–308.
- Treebank data
- Joakim Nivre, Marie-Catherine de Marneffe, Filip Ginter, Jan Hajič, Christopher Manning, Sampo Pyysalo, Sebastian Schuster, Francis Tyers, and Daniel Zeman (2020). Universal Dependencies v2: An Evergrowing Multilingual Treebank Collection. Proceedings of the 12th International Conference on Language Resources and Evaluation (LREC 2020), pp. 4034–4043, Marseille, France.
Current UD Languages
Information about language families (and genera for families with multiple branches) is mostly taken from WALS Online (IE = Indo-European).
 Abaza
1
<1K
Northwest Caucasian
Abaza treebanks
ATB
<1K

- Contributors: Alexey Koshevoy, Anastasia Panova, Ilya Makarchuk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Abkhaz
1
14K
Northwest Caucasian
Abkhaz treebanks
AbNC
14K
- Contributors: Paul Meurer
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Afrikaans
1
49K
IE, Germanic
Afrikaans treebanks
AfriBooms
49K
- Contributors: Peter Dirix, Liesbeth Augustinus, Daniel van Niekerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Akkadian
2
25K
Afro-Asiatic, Semitic
Akkadian treebanks
RIAO
23K
- Contributors: Mikko Luukko, Aleksi Sahala, Sam Hardwick, Krister Lindén
- Repository master dev
- README
- Treebank hub page
- Download
PISANDUB
1K
- Contributors: Kamil Kopacewicz
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Akuntsu
1
1K
Tupian, Tupari
Akuntsu treebanks
TuDeT
1K
- Contributors: Carolina Aragon, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Albanian
2
4K
IE, Albanian
Albanian treebanks
TSA
<1K
- Contributors: Marsida Toska
- Repository master dev
- README
- Treebank hub page
- Download
STAF
3K
- Contributors: Luigi Talamo, Edita Luftiu, Nelda Kote, Rozana Rushiti, Anila Çepani
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Alemannic
2
21K
IE, Germanic
Alemannic treebanks
DIVITAL
19K
- Contributors: Nathanaël Beiner, Barbara Hoff, Delphine Bernhard
- Repository master dev
- README
- Treebank hub page
- Download
UZH
1K
- Contributors: Noëmi Aepli
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Amharic
1
10K
Afro-Asiatic, Semitic
Amharic treebanks
ATT
10K
- Contributors: Binyam Ephrem, Gashaw Arutie, Tsegay Woldemariam, Juan Ignacio Navarro Horñiacek
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ancient Greek
3
456K
IE, Greek
Ancient Greek treebanks
PTNK
39K
- Contributors: Daniel Swanson
- Repository master dev
- README
- Treebank hub page
- Download
PROIEL
214K

- Contributors: Dag Haug
- Repository master dev
- README
- Treebank hub page
- Download
Perseus
202K
- Contributors: Giuseppe G. A. Celano, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ancient Hebrew
1
145K
Afro-Asiatic, Semitic
Ancient Hebrew treebanks
PTNK
145K

- Contributors: Daniel Swanson
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Apurina
1
1K
Arawakan, Purus
Apurina treebanks
UFPA
1K
- Contributors: Marília Fernanda, Sidney Facundes, Bruna Lima Padovani, Jack Rueter, Niko Partanen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Arabic
3
1,042K
Afro-Asiatic, Semitic
Arabic treebanks
PUD
20K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Luma Ateyah, Martin Popel, Daniel Zeman, Nizar Habash, Dima Taji
- Repository master dev
- README
- Treebank hub page
- Download
PADT
282K
- Contributors: Daniel Zeman, Zdeněk Žabokrtský, Shadi Saleh
- Repository master dev
- README
- Treebank hub page
- Download
NYUAD
738K
- Contributors: Nizar Habash, Dima Taji
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Armenian
2
150K
IE, Armenian
Armenian treebanks
ArmTDP
104K
- Contributors: Marat M. Yavrumyan
- Repository master dev
- README
- Treebank hub page
- Download
BSUT
46K
- Contributors: Marat M. Yavrumyan
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Assamese
1
<1K
IE, Indic
Assamese treebanks
AiW
<1K
- Contributors: Kaushik Sengupta, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Assyrian
1
<1K
Afro-Asiatic, Semitic
Assyrian treebanks
AS
<1K
- Contributors: Mary Yako
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Avestan
1
<1K
IE, Iranian
Avestan treebanks
Old
<1K
- Contributors: Peter Dirix
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Azerbaijani
1
<1K
Turkic, Southwestern
Azerbaijani treebanks
TueCL
<1K
- Contributors: Soudabeh Eslami, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bambara
1
13K
Mande
Bambara treebanks
CRB
13K
- Contributors: Katya Aplonova, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Basque
1
121K
Basque
Basque treebanks
BDT
121K
- Contributors: Maria Jesus Aranzabe, Aitziber Atutxa, Kepa Bengoetxea, Arantza Diaz de Ilarraza, Iakes Goenaga, Koldo Gojenola, Larraitz Uria
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bavarian
1
15K
IE, Germanic
Bavarian treebanks
MaiBaam
15K
- Contributors: Verena Blaschke, Barbara Kovačić, Siyao Peng, Miriam Winkler, Barbara Plank
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Beja
1
11K
Afro-Asiatic, Cushitic
Beja treebanks
Autogramm
11K
- Contributors: Martine Vanhove, Rayan Ziane, Sylvain Kahane, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Belarusian
1
305K
IE, Slavic
Belarusian treebanks
HSE
305K
- Contributors: Olga Lyashevskaya, Angelika Peljak-Łapińska, Daria Petrova, Yana Shishkina
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bengali
1
<1K
IE, Indic
Bengali treebanks
BRU
<1K
- Contributors: Siratun Jannat, Mizanur Rahoman, Shafi Sourov, Jannatul Ferdaousi, Syeda Shahzadi, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Bhojpuri
1
6K
IE, Indic
Bhojpuri treebanks
BHTB
6K
- Contributors: Atul Kr. Ojha, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bokota
1
2K
Chibchan, Guaymiic
Bokota treebanks
ChibErgIS
2K
- Contributors: Marie Benzerrak, Natalia Cáceres Arandia
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bonan
1
8K
Mongolic
Bonan treebanks
GDUD
8K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Bororo
1
160K
Bororoan
Bororo treebanks
BDT
160K
- Contributors: Fabrício Ferraz Gerardi, Lucas Toribio, Dolores Sollberger
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Brahui
1
<1K
Dravidian
Brahui treebanks
Kholum
<1K
- Contributors: Muhammad Afzal, Luigi Talamo, Helena Vaz, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Breton
1
10K
IE, Celtic
Breton treebanks
KEB
10K
- Contributors: Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Bulgarian
1
156K
IE, Slavic
Bulgarian treebanks
BTB
156K
- Contributors: Kiril Simov, Petya Osenova, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Buryat
1
10K
Mongolic
Buryat treebanks
BDT
10K
- Contributors: Elena Badmaeva, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Cantonese
1
13K
Sino-Tibetan, Chinese
Cantonese treebanks
HK
13K
- Contributors: Kim Gerdes, John Lee, Herman Leung, Tak-sum Wong
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Cappadocian
2
4K
IE, Greek
Cappadocian treebanks
AMGiC
<1K
- Contributors: Konstantinos Sampanis, Prokopis Prokopidis, Furkan Akkurt, Helin Binici
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
4K
- Contributors: Eleni Vligouridou, Inessa Iliadou, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Catalan
1
547K
IE, Romance
Catalan treebanks
AnCora
547K

- Contributors: Héctor Martínez Alonso, Elena Pascual, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Cebuano
1
1K
Austronesian, Greater Central Philippine
Cebuano treebanks
GJA
1K
- Contributors: Glyd Aranes
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Central Kurdish
1
<1K
IE, Iranian
Central Kurdish treebanks
Mukri
<1K
- Contributors: Hiwa Asadpour, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Chechen
1
3K
Nakh-Daghestanian, Nakh
Chechen treebanks
MottDT
3K
- Contributors: Anna Veselovsky, Zarina Molochieva, Alena Witzlack-Makarevich
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Chinese
7
309K
Sino-Tibetan, Chinese
Chinese treebanks
GSDSimp
123K
- Contributors: Peng Qi, Koichi Yasuoka
- Repository master dev
- README
- Treebank hub page
- Download
GSD
123K
- Contributors: Mo Shen, Ryan McDonald, Daniel Zeman, Peng Qi
- Repository master dev
- README
- Treebank hub page
- Download
Beginner
19K
- Contributors: Kirian Guiller, Yidi Huang, Yixuan Li, Qishen Wu, Bruno Guillaume, Sylvain Kahane, Kim Gerdes
- Repository master dev
- README
- Treebank hub page
- Download
PatentChar
4K
- Contributors: Yixuan Li, Kim Gerdes, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
PUD
21K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Josie Li, Cheuk Ying Li, Martin Popel, Daniel Zeman, Herman Leung
- Repository master dev
- README
- Treebank hub page
- Download
HK
9K
- Contributors: Kim Gerdes, John Lee, Herman Leung, Tak-sum Wong
- Repository master dev
- README
- Treebank hub page
- Download
CFL
7K
- Contributors: John Lee, Herman Leung, Keying Li
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Chintang
1
14K
Sino-Tibetan, Himalayish
Chintang treebanks
CTNTB
14K
- Contributors: Kira Tulchynska, Robert Schikowski, Alena Witzlack-Makarevich
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Chukchi
1
6K
Chukotko-Kamchatkan
Chukchi treebanks
HSE
6K
- Contributors: Francis Tyers, Karina Mischenkova
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Classical Armenian
1
99K
IE, Armenian
Classical Armenian treebanks
CAVaL
99K
- Contributors: Petr Kocharov, Lilit Kharatyan
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Classical Chinese
2
433K
Sino-Tibetan, Chinese
Classical Chinese treebanks
Kyoto
433K
?
- Contributors: Koichi Yasuoka, Christian Wittern, Tomohiko Morioka, Takumi Ikeda, Naoki Yamazaki, Yoshihiro Nikaido, Shingo Suzuki, Shigeki Moro, Yuan Li, Hiroyuki Shirasu, Kazunori Fujita
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
<1K
- Contributors: Yifei Chen, John Wang, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Coptic
2
91K
Afro-Asiatic, Egyptian
Coptic treebanks
Scriptorium
58K
- Contributors: Mitchell Abrams, Elizabeth Davidson, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
Bohairic
32K
- Contributors: Amir Zeldes, Nina Speransky
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Croatian
1
199K
IE, Slavic
Croatian treebanks
SET
199K
- Contributors: Tanja Samardžić, Aleksandra Miletić, Nikola Ljubešić, Željko Agić, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Cuicatec
1
9K
Oto-Manguean
Cuicatec treebanks
MesoTree
9K
- Contributors: Robert Pugh, Francis Tyers, Lucía Lezama Tejada, Mazali Madai Herrera Ojeda, María Lilia Herrera Ojeda
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Czech
7
4,172K
IE, Slavic
Czech treebanks
PDTC
3,440K
- Contributors: Daniel Zeman, Jan Hajič, Alevtina Bémová, Eva Buráňová, Eva Hajičová, Jiří Havelka, Jaroslava Hlaváčová, Jiří Kárník, Veronika Kolářová, Lucie Kučová, Markéta Lopatková, Marie Mikulová, Jiří Mírovský, Anna Nedoluzhko, Michal Novák, Petr Pajas, Jarmila Panevová, Petr Sgall, Milan Straka, Magda Ševčíková, Jan Štěpánek, Barbora Štěpánková, Zdeňka Urešová, Barbora Vidová Hladká, Zdeněk Žabokrtský
- Repository master dev
- README
- Treebank hub page
- Download
CAC
494K
- Contributors: Barbora Hladká, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
FicTree
167K
- Contributors: Tomáš Jelínek, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
CLTT
36K
- Contributors: Barbora Hladká, Daniel Zeman, Martin Popel
- Repository master dev
- README
- Treebank hub page
- Download
CzeSL
9K
- Contributors: Jiří Hana, Barbora Hladká, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
PUD
18K
- Contributors: Václava Kettnerová, Jan Hajič jr., Silvie Cinková, Zdeňka Urešová, Milan Straka, Jan Hajič, Jaroslava Hlaváčová, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Poetry
6K
- Contributors: Silvie Cinková
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Danish
1
100K
IE, Germanic
Danish treebanks
DDT
100K
- Contributors: Anders Johannsen, Héctor Martínez Alonso, Barbara Plank
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Dargwa
1
4K
Nakh-Daghestanian, Lak-Dargwa
Dargwa treebanks
Mehweb
4K
- Contributors: Olga Lyashevskaya
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Daur
1
<1K
Mongolic
Daur treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Dongxiang
1
<1K
Mongolic
Dongxiang treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Dutch
2
505K
IE, Germanic
Dutch treebanks
LassySmall
297K
- Contributors: Gosse Bouma, Gertjan van Noord
- Repository master dev
- README
- Treebank hub page
- Download
Alpino
208K
- Contributors: Daniel Zeman, Zdeněk Žabokrtský, Gosse Bouma, Gertjan van Noord
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Egyptian
1
42K
Afro-Asiatic, Egyptian
Egyptian treebanks
PC
42K
- Contributors: Roberto Antonio Díaz Hernández, Bruno Guillaume, Daniel Zeman, Valentina Anselmi, Haleli Harel, Johannes Nikolaus Heinrich Schmitt
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 English
14
1,224K
IE, Germanic
English treebanks
GUM
256K
- Contributors: Siyao Peng, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
EWT
254K
- Contributors: Natalia Silveira, Timothy Dozat, Christopher Manning, Sebastian Schuster, Ethan Chi, John Bauer, Miriam Connor, Marie-Catherine de Marneffe, Nathan Schneider, Sam Bowman, Hanzhi Zhu, Daniel Galbraith, John Bauer
- Repository master dev
- README
- Treebank hub page
- Download
LinES
106K
- Contributors: Lars Ahrenberg
- Repository master dev
- README
- Treebank hub page
- Download
ParTUT
49K
- Contributors: Cristina Bosco, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
Atis
61K
- Contributors: Aslı Kuzgun, Neslihan Cesur, Olcay Taner Yıldız
- Repository master dev
- README
- Treebank hub page
- Download
GENTLE
17K
- Contributors: Tatsuya Aoyama, Shabnam Behzad, Luke Gessler, Lauren Levine, Yi-Ju Jessica Lin, Yang Janet Liu, Siyao Logan Peng, Yilun Zhu, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
CHILDES
302K
- Contributors: Xiulin Yang, Zhuoxuan Ju, Lanni Bu, Zoey Liu, Nathan Schneider
- Repository master dev
- README
- Treebank hub page
- Download
LittlePrince
6K
- Contributors: Lori Levin, Annie Zhang, Thomas Palakapilly, Jack Sun, Larry Zhang
- Repository master dev
- README
- Treebank hub page
- Download
PUD
21K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Jesse Kirchner, Lorenzo Lambertino, Martin Popel, Daniel Zeman, Christopher Manning, Sebastian Schuster, Siva Reddy
- Repository master dev
- README
- Treebank hub page
- Download
CTeTex
9K
- Contributors: Naïma Hassert, Pierre André Ménard, Edith Galy
- Repository master dev
- README
- Treebank hub page
- Download
Pronouns
1K
- Contributors: Robert Munro
- Repository master dev
- README
- Treebank hub page
- Download
ESL
97K
- Contributors: Yevgeni Berzak, Jessica Kenney, Carolyn Spadine, Jing Xian Wang, Lucia Lam, Keiko Sophie Mori, Sebastian Garza, Boris Katz, Margarita Misirpashayeva, Rivkah Bazlov
- Repository master dev
- README
- Treebank hub page
- Download
GUMReddit
16K
- Contributors: Siyao Peng, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
ESLSpok
21K
- Contributors: Kris Kyle, Masaki Eguchi, Aaron Miller, Ted Sither
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Erzya
1
20K
Uralic, Mordvin
Erzya treebanks
JR
20K
- Contributors: Jack Rueter, Francis Tyers, Elena Klementieva, Olga Erina, Ivan Riabov
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Esperanto
2
4K
Constructed
Esperanto treebanks
Prago
3K
- Contributors: Masanori Oya
- Repository master dev
- README
- Treebank hub page
- Download
Cairo
<1K
- Contributors: Masanori Oya
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Estonian
2
528K
Uralic, Finnic
Estonian treebanks
EDT
437K
- Contributors: Kadri Muischnek, Kaili Müürisep, Tiina Puolakainen, Andriela Rääbis, Liisi Torga
- Repository master dev
- README
- Treebank hub page
- Download
EWT
90K
- Contributors: Kadri Muischnek, Kaili Müürisep, Tiina Puolakainen, Dage Särg, Sandra Eiche, Andriela Rääbis
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Even
1
<1K
Tungusic
Even treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Evenki
1
<1K
Tungusic
Evenki treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Faroese
2
50K
IE, Germanic
Faroese treebanks
OFT
10K
- Contributors: Daniel Zeman, Bjartur Mortensen, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
FarPaHC
40K
- Contributors: Þórunn Arnardóttir, Hinrik Hafsteinsson, Einar Freyr Sigurðsson, Anton Karl Ingason, Eiríkur Rögnvaldsson, Joel C. Wallenberg
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Finnish
4
397K
Uralic, Finnic
Finnish treebanks
TDT
202K
- Contributors: Filip Ginter, Jenna Kanerva, Veronika Laippala, Niko Miekka, Anna Missilä, Stina Ojala, Sampo Pyysalo
- Repository master dev
- README
- Treebank hub page
- Download
FTB
159K
- Contributors: Jussi Piitulainen, Hanna Nurmi, Jack Rueter
- Repository master dev
- README
- Treebank hub page
- Download
OOD
19K
- Contributors: Jenna Kanerva
- Repository master dev
- README
- Treebank hub page
- Download
PUD
15K
- Contributors: Jenna Kanerva, Filip Ginter, Stina Ojala, Anna Missilä
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 French
9
708K
IE, Romance
French treebanks
GSD
400K
- Contributors: Marie-Catherine de Marneffe, Bruno Guillaume, Ryan McDonald, Alane Suhr, Joakim Nivre, Matias Grioni, Carly Dickerson, Guy Perrier
- Repository master dev
- README
- Treebank hub page
- Download
ALTS
68K
- Contributors: Natasha Romanova, Rayan Ziane, Khensa Daoudi, Théo Brillet
- Repository master dev
- README
- Treebank hub page
- Download
Sequoia
70K

- Contributors: Marie Candito, Djamé Seddah, Guy Perrier, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
ParisStories
42K
- Contributors: Kim Gerdes, Sylvain Kahane, Menel Mahamdi, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
Rhapsodie
44K
- Contributors: Kim Gerdes, Sylvain Kahane, Mariam Nakhlé, Chunxiao Yan, Aline Etienne, Marine Courtin, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
ParTUT
28K
- Contributors: Cristina Bosco, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
PUD
24K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Jana Strnadová, Gauthier Caron, Martin Popel, Daniel Zeman, Marie-Catherine de Marneffe, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
FQB
23K
- Contributors: Djamé Seddah, Marie Candito, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
PoitevinDIVITAL
5K
- Contributors: Marianne Vergez-Couret
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
French Sign Language
1
<1K
Sign Language
French Sign Language treebanks
STKAutogramm
<1K
- Contributors: Sylvain Kahane, Santiago Herrera, Philomène Périn, Caroline Bogliotti, Lou Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Frisian Dutch
1
3K
Code switching
Frisian Dutch treebanks
Fame
3K
- Contributors: Anouck Braggaar, Rob van der Goot
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Galician
3
188K
IE, Romance
Galician treebanks
TreeGal
25K
- Contributors: Marcos Garcia, Xulia Sánchez-Rodríguez, Albina Sarymsakova
- Repository master dev
- README
- Treebank hub page
- Download
PUD
23K
- Contributors: Albina Sarymsakova, Xulia Sánchez-Rodríguez, Helena Pérez Puente, Marcos Garcia
- Repository master dev
- README
- Treebank hub page
- Download
CTG
139K
- Contributors: Xavier Gómez Guinovart
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Gedeo
1
<1K
Afro-Asiatic, Cushitic
Gedeo treebanks
GDT
<1K
- Contributors: Dawit J. Tilahun
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Georgian
2
83K
Kartvelian
Georgian treebanks
GNC
23K
- Contributors: Paul Meurer
- Repository master dev
- README
- Treebank hub page
- Download
GLC
60K
- Contributors: Irina Lobzhanidze
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 German
4
3,810K
IE, Germanic
German treebanks
HDT
3,455K
- Contributors: Emanuel Borges Völker, Felix Hennig, Arne Köhn, Maximilan Wendt, Verena Blaschke, Nina Böbel, Jacob Lee Suchardt, Leonie Weissweiler
- Repository master dev
- README
- Treebank hub page
- Download
GSD
292K
- Contributors: Slav Petrov, Wolfgang Seeker, Ryan McDonald, Joakim Nivre, Daniel Zeman, Adriane Boyd, Verena Blaschke
- Repository master dev
- README
- Treebank hub page
- Download
PUD
21K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Georg Rehm, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Michael Mandl, Sebastian Bank, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
LIT
40K
- Contributors: Alessio Salomoni
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Gheg
1
15K
IE, Albanian
Gheg treebanks
GPS
15K
- Contributors: Christian Ebert, Artan Islamaj, Adrian Kuqi, Barbara Sonnenhauser, Paul Widmer, Magdalena Plamada
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Gorani
1
<1K
IE, Iranian
Gorani treebanks
Hawrami
<1K
- Contributors: Amirhossein Mojiri Foroushani, Zaniar Ghaderi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Gorontalo
1
<1K
Austronesian, Greater Central Philippine
Gorontalo treebanks
BungoLoLombi
<1K
- Contributors: Andrew Thomas Dyer, Colleen Alena O'Brien
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Gothic
1
55K
IE, Germanic
Gothic treebanks
PROIEL
55K
- Contributors: Dag Haug
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Greek
8
114K
IE, Greek
Greek treebanks
GDT
63K
- Contributors: Prokopis Prokopidis
- Repository master dev
- README
- Treebank hub page
- Download
GUD
25K
- Contributors: Stella Markantonatou, Stavros Bompolas, Vivian Stamou, Socrates Vak
- Repository master dev
- README
- Treebank hub page
- Download
Lesbian
6K
- Contributors: Stavros Bompolas, Stella Markantonatou, Antonios Anastasopoulos
- Repository master dev
- README
- Treebank hub page
- Download
Cretan
4K
- Contributors: Socrates Vakirtzian, Stella Markantonatou, Vivian Stamou
- Repository master dev
- README
- Treebank hub page
- Download
GLCII
9K
- Contributors: Christina Klironomou, Thelka Pasparaki, Arianna Masciolini
- Repository master dev
- README
- Treebank hub page
- Download
Cypriot
2K
- Contributors: Stella Markantonatou, Spyros Armostis, Stavros Bompolas, Antonis Dimakis, Maria Apostolidou, Eirini Chalkia, Konstantinos Raftis, Christina-Athanasia Petropoulou, Dionisis Piskopos
- Repository master dev
- README
- Treebank hub page
- Download
Griko
1K
- Contributors: Stella Markantonatou, Emanuela Pinna, Stavros Bompolas, Maria Lekakou, Josep Quer
- Repository master dev
- README
- Treebank hub page
- Download
Messinian
<1K
- Contributors: Stella Markantonatou, Katerina Mouzou, Vivian Stamou
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Guajajara
1
9K
Tupian, Maweti-Guarani
Guajajara treebanks
TuDeT
9K
- Contributors: Lorena Martín Rodríguez, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Guarani
1
<1K
Tupian, Maweti-Guarani
Guarani treebanks
OldTuDeT
<1K
- Contributors: Fabrício Ferraz Gerardi, Lorena Martín Rodríguez
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Gujarati
2
2K
IE, Indic
Gujarati treebanks
ShabdaSetu
<1K
- Contributors: Dhairushi Patel, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
GujTB
1K
- Contributors: Maitrey Mehta, Mayank Jobanputra
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Gwichin
1
1K
Na-Dene
Gwichin treebanks
TueCL
1K
- Contributors: Matthew Andrews, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Haitian Creole
2
75K
Creole
Haitian Creole treebanks
Autogramm
3K
- Contributors: Claudel Pierre-Louis, Sandra Jagodzińska, Sylvain Kahane, Agata Savary, Emmanuel Schang
- Repository master dev
- README
- Treebank hub page
- Download
Adolphe
71K
- Contributors: Jephtey Adolphe
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Hausa
4
53K
Afro-Asiatic, West Chadic
Hausa treebanks
EasternAutogramm
9K
- Contributors: Bernard Caron
- Repository master dev
- README
- Treebank hub page
- Download
WesternAutogramm
13K
- Contributors: Bernard Caron
- Repository master dev
- README
- Treebank hub page
- Download
NorthernAutogramm
15K
- Contributors: Bernard Caron
- Repository master dev
- README
- Treebank hub page
- Download
SouthernAutogramm
14K
- Contributors: Bernard Caron
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Hebrew
4
376K
Afro-Asiatic, Semitic
Hebrew treebanks
IAHLTwiki
140K
- Contributors: Amir Zeldes, Avner Algom, Noam Ordan, Yifat Ben Moshe, Shira Wigderson
- Repository master dev
- README
- Treebank hub page
- Download
IAHLTknesset
67K
- Contributors: Amir Zeldes, Avner Algom, Noam Ordan, Yifat Ben Moshe, Nick Howell, Shira Wigderson, Omer Strass, Israel Landau, Netanel Dahan, Yael Minerbi, Hilla Merhav, Emmanuelle Kowner, Shuly Wintner, Gili Goldin, Ella Rabinovich, Vladimir Gurevich
- Repository master dev
- README
- Treebank hub page
- Download
HTB
160K
- Contributors: Yoav Goldberg, Reut Tsarfaty, Amir More, Shoval Sadde, Victoria Basmov, Yuval Pinter
- Repository master dev
- README
- Treebank hub page
- Download
PostRab
8K
- Contributors: Rachel Tal, Elisheva Brauner, Shlomit Fuchs, Orly Albek, Avi Shmidman, Yitzchak Lindenbaum, Ephraim Meiri
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Highland P. Nahuatl
1
10K
Uto-Aztecan
Highland Puebla Nahuatl treebanks
ITML
10K
- Contributors: Robert Pugh, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Hindi
2
375K
IE, Indic
Hindi treebanks
HDTB
351K
- Contributors: Riyaz Ahmad Bhat, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
PUD
23K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Esha Banerjee, Pinkey Nainwani, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Hittite
1
1K
IE, Anatolian
Hittite treebanks
HitTB
1K
- Contributors: Erik Andersen, Ben Rozonoyer
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Hungarian
1
42K
Uralic, Ugric
Hungarian treebanks
Szeged
42K
- Contributors: Richárd Farkas, Katalin Simkó, Zsolt Szántó, Viktor Varga, Veronika Vincze
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Icelandic
4
1,183K
IE, Germanic
Icelandic treebanks
IcePaHC
985K
- Contributors: Þórunn Arnardóttir, Hinrik Hafsteinsson, Einar Freyr Sigurðsson, Hildur Jónsdóttir, Kristín Bjarnadóttir, Anton Karl Ingason, Kristján Rúnarsson, Steinþór Steingrímsson, Joel C. Wallenberg, Eiríkur Rögnvaldsson
- Repository master dev
- README
- Treebank hub page
- Download
Modern
80K
- Contributors: Kristján Rúnarsson, Þórunn Arnardóttir, Hinrik Hafsteinsson, Starkaður Barkarson, Hildur Jónsdóttir, Steinþór Steingrímsson, Einar Freyr Sigurðsson
- Repository master dev
- README
- Treebank hub page
- Download
GC
99K
- Contributors: Vilhjálmur Þorsteinsson, Hulda Óladóttir, Þórunn Arnardóttir, Sveinbjörn Þórðarson, Haukur Barri Símonarson, Katla Ásgeirsdóttir
- Repository master dev
- README
- Treebank hub page
- Download
PUD
18K
- Contributors: Hildur Jónsdóttir
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ika
1
5K
Chibchan, Arhuacic
Ika treebanks
ChibErgIS
5K
- Contributors: Jana Bajorat, Natalia Cáceres Arandia
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Indonesian
3
169K
Austronesian, Malayo-Sumbawan
Indonesian treebanks
PUD
19K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Ruli Manurung, Muh Shohibussirri, Martin Popel, Daniel Zeman, Ika Alfina, Arawinda Dinakaramani, Muhammad Yudistira Hanifmuti, Jessica Naraiswari Arwidarasti, Yogi Lesmana Sulestio
- Repository master dev
- README
- Treebank hub page
- Download
GSD
122K
- Contributors: Ryan McDonald, Joakim Nivre, Daniel Zeman, Septina Dian Larasati, Ika Alfina
- Repository master dev
- README
- Treebank hub page
- Download
CSUI
28K
- Contributors: Ika Alfina, Jessica Naraiswari Arwidarasti, Muhammad Yudistira Hanifmuti, Arawinda Dinakaramani, Ruli Manurung, Fam Rashel, Andry Luthfi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Irish
3
168K
IE, Celtic
Irish treebanks
IDT
115K
- Contributors: Teresa Lynn, Jennifer Foster, Sarah McGuinness, Abigail Walsh, Jason Phelan, Kevin Scannell
- Repository master dev
- README
- Treebank hub page
- Download
TwittIrish
47K
- Contributors: Lauren Cassidy, Teresa Lynn, Jennifer Foster, Sarah McGuinness
- Repository master dev
- README
- Treebank hub page
- Download
Cadhan
4K
- Contributors: Kevin Scannell, Theodorus Fransen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Italian
11
1,026K
IE, Romance
Italian treebanks
ISDT
298K
- Contributors: Cristina Bosco, Alessandro Lenci, Simonetta Montemagni, Maria Simi
- Repository master dev
- README
- Treebank hub page
- Download
VIT
280K
- Contributors: Fabio Tamburini, Maria Simi, Cristina Bosco
- Repository master dev
- README
- Treebank hub page
- Download
Old
122K
- Contributors: Claudia Corbetta, Marco Passarotti, Flavio Massimiliano Cecchini, Giovanni Moretti
- Repository master dev
- README
- Treebank hub page
- Download
KIParlaForest
24K
- Contributors: Ludovica Pannitto, Eleonora Zucchini, Cristina Bosco, Caterina Mauri, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
Valico
6K
- Contributors: Elisa Di Nuovo, Manuela Sanguinetti, Cristina Bosco, Alessandro Mazzei
- Repository master dev
- README
- Treebank hub page
- Download
ParlaMint
20K
- Contributors: Chiara Alzetta, Marta Sartor, Simonetta Montemagni, Giulia Venturi
- Repository master dev
- README
- Treebank hub page
- Download
ParTUT
55K
- Contributors: Cristina Bosco, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
TWITTIRO
29K
- Contributors: Alessandra T. Cignarella, Cristina Bosco, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
PoSTWITA
124K
- Contributors: Cristina Bosco, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
PUD
23K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Antonio Stella, Davide Rovati, Martin Popel, Daniel Zeman, Maria Simi, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
MarkIT
40K
- Contributors: Teresa Paccosi, Alessio Palmero Aprosio, Sara Tonelli
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Japanese
6
2,645K
Japanese
Japanese treebanks
GSD
193K
- Contributors: Mai Omura, Yusuke Miyao, Hiroshi Kanayama, Hiroshi Matsuda, Aya Wakasa, Kayo Yamashita, Masayuki Asahara, Takaaki Tanaka, Yugo Murawaki, Yuji Matsumoto, Shinsuke Mori, Sumire Uematsu, Ryan McDonald, Joakim Nivre, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
GSDLUW
150K
- Contributors: Mai Omura, Yusuke Miyao, Hiroshi Kanayama, Hiroshi Matsuda, Aya Wakasa, Kayo Yamashita, Masayuki Asahara, Takaaki Tanaka, Yugo Murawaki, Yuji Matsumoto, Shinsuke Mori, Sumire Uematsu, Ryan McDonald, Joakim Nivre, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
PUD
28K
- Contributors: Mai Omura, Yusuke Miyao, Hiroshi Kanayama, Hiroshi Matsuda, Aya Wakasa, Kayo Yamashita, Masayuki Asahara, Takaaki Tanaka, Yugo Murawaki, Yuji Matsumoto, Kaoru Ito, Taishi Chika, Shinsuke Mori, Sumire Uematsu, Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Atsuko Shimada, Anna Trukhina, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
PUDLUW
22K
- Contributors: Mai Omura, Yusuke Miyao, Hiroshi Kanayama, Hiroshi Matsuda, Aya Wakasa, Kayo Yamashita, Masayuki Asahara, Takaaki Tanaka, Yugo Murawaki, Yuji Matsumoto, Kaoru Ito, Taishi Chika, Shinsuke Mori, Sumire Uematsu, Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Atsuko Shimada, Anna Trukhina, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
BCCWJ
1,253K
- Contributors: Mai Omura, Masayuki Asahara, Yusuke Miyao, Takaaki Tanaka, Hiroshi Kanayama, Yuji Matsumoto, Shinsuke Mori, Sumire Uematsu, Yugo Murawaki
- Repository master dev
- README
- Treebank hub page
- Download
BCCWJLUW
995K
- Contributors: Mai Omura, Masayuki Asahara, Yusuke Miyao, Takaaki Tanaka, Hiroshi Kanayama, Yuji Matsumoto, Shinsuke Mori, Sumire Uematsu, Yugo Murawaki
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Javanese
1
14K
Austronesian, Javanese
Javanese treebanks
CSUI
14K
- Contributors: Ika Alfina, Arlisa Yuliawati, Dipta Tanaya, Arawinda Dinakaramani, Daniel Zeman, Putri Rizqiyah, Sri Hartati Wijono, Rangga Prangwedana Prangwedana
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Kaapor
1
<1K
Tupian, Maweti-Guarani
Kaapor treebanks
TuDeT
<1K
- Contributors: Fabrício Ferraz Gerardi, Carolina Aragon, Gustavo Godoy
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Kadiweu
1
<1K
Guaicuruan
Kadiweu treebanks
Unicamp
<1K
- Contributors: Filomena Spatti Sandalo, Leonel Figueiredo de Alencar, Charlotte Chambelland Galves, Luiz Veronesi, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Kalmyk
1
<1K
Mongolic
Kalmyk treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Kangri
1
2K
IE, Indic
Kangri treebanks
KDTB
2K
- Contributors: Shweta Chauhan, Shefali Saxena, Apoorva Jha, Philemon Daniel
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Karelian
1
3K
Uralic, Finnic
Karelian treebanks
KKPP
3K
- Contributors: Tommi A Pirinen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Karo
1
2K
Tupian, Ramarama
Karo treebanks
TuDeT
2K
- Contributors: Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Kashmiri
1
2K
IE, Indic
Kashmiri treebanks
Zaan
2K
- Contributors: Rimsha Abid, Hiwa Asadpour, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Kazakh
1
10K
Turkic, Northwestern
Kazakh treebanks
KTB
10K
- Contributors: Aibek Makazhanov, Jonathan North Washington, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Khoekhoe
1
29K
Khoe-Kwadi
Khoekhoe treebanks
KDT
29K
- Contributors: Kira Tulchynska, Alena Witzlack-Makarevich, Sylvanus Job, Michael Hahn
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Kiche
1
10K
Mayan
Kiche treebanks
IU
10K
- Contributors: Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Komi Permyak
1
1K
Uralic, Permic
Komi Permyak treebanks
UH
1K
- Contributors: Larisa Ponomareva, Niko Partanen, Jack Rueter, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Komi Zyrian
2
10K
Uralic, Permic
Komi Zyrian treebanks
Lattice
8K
- Contributors: Niko Partanen, KyungTae Lim, Thierry Poibeau, Jack Rueter
- Repository master dev
- README
- Treebank hub page
- Download
IKDP
2K
- Contributors: Niko Partanen, Rogier Blokland, Michael Rießler, Jack Rueter
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Korean
5
615K
Korean
Korean treebanks
Kaist
350K
- Contributors: Jinho Choi, Na-Rae Han, Jena Hwang, Jayeol Chun
- Repository master dev
- README
- Treebank hub page
- Download
KSL
155K
- Contributors: Hakyung Sung, Gyu-Ho Shin
- Repository master dev
- README
- Treebank hub page
- Download
GSD
80K
- Contributors: Ryan McDonald, Joakim Nivre, Daniel Zeman, Jinho Choi, Na-Rae Han, Jena Hwang, Jayeol Chun
- Repository master dev
- README
- Treebank hub page
- Download
PUD
16K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Sookyoung Kwak, Yongseok Cho, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
LittlePrince
13K
- Contributors: Junghyun Min, Jena Hwang, Nathan Schneider
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Kullvi
1
4K
IE, Indic
Kullvi treebanks
KDTB
4K
- Contributors: Shweta Chauhan, Shefali Saxena, Shweta Jain
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Kyrgyz
2
25K
Turkic, Northwestern
Kyrgyz treebanks
KTMU
24K
- Contributors: İbrahim Benli
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
1K
- Contributors: Bermet Chontaeva, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Latgalian
1
<1K
IE, Baltic
Latgalian treebanks
Cairo
<1K
- Contributors: Lauma Pretkalniņa, Gunta Nešpore-Bērzkalne
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Latin
6
1,012K
IE, Italic
Latin treebanks
ITTB
450K
- Contributors: Marco Passarotti, Marinella Testori, Daniel Zeman, Berta González Saavedra, Flavio Massimiliano Cecchini
- Repository master dev
- README
- Treebank hub page
- Download
LLCT
242K
- Contributors: Timo Korkiakangas, Flavio Massimiliano Cecchini, Marco Passarotti
- Repository master dev
- README
- Treebank hub page
- Download
UDante
55K
- Contributors: Flavio Massimiliano Cecchini, Giovanni Moretti, Marco Passarotti, Rachele Sprugnoli, Daniela Corbetta, Federica Favero, Federica Gamba, Martina de Laurentiis, Giulia Pedonese, Andrea Peverelli, Elena Vagnoni, Mirko Tavoni
- Repository master dev
- README
- Treebank hub page
- Download
CIRCSE
29K
- Contributors: Federica Iurescia, Federica Gamba, Flavio Massimiliano Cecchini, Francesco Mambrini, Giovanni Moretti, Marco Passarotti, Paolo Ruffolo
- Repository master dev
- README
- Treebank hub page
- Download
Perseus
29K
- Contributors: Giuseppe G. A. Celano, Daniel Zeman, Federica Gamba
- Repository master dev
- README
- Treebank hub page
- Download
PROIEL
205K
- Contributors: Dag Haug
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Latvian
2
330K
IE, Baltic
Latvian treebanks
LVTB
330K
- Contributors: Lauma Pretkalniņa, Laura Rituma, Gunta Nešpore-Bērzkalne, Baiba Saulīte, Artūrs Znotiņš, Normunds Grūzītis
- Repository master dev
- README
- Treebank hub page
- Download
Cairo
<1K
- Contributors: Lauma Pretkalniņa, Laura Rituma, Baiba Saulīte, Gunta Nešpore-Bērzkalne
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Laz
1
2K
Kartvelian
Laz treebanks
BOUN
2K
- Contributors: Utku Türk, Kaan Bayar, Ayşegül Dilara Özercan, Görkem Yiğit Öztürk, Betül Bilgin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ligurian
1
6K
IE, Romance
Ligurian treebanks
GLT
6K
?
- Contributors: Stefano Lusito, Jean Maillard
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Lithuanian
2
61K
IE, Baltic
Lithuanian treebanks
ALKSNIS
56K
- Contributors: Andrius Utka, Erika Rimkutė, Agnė Bielinskienė, Jolanta Kovalevskaitė, Loïc Boizou, Gabrielė Aleksandravičiūtė, Kristina Brokaitė, Daniel Zeman, Natalia Perkova, Bernadeta Griciūtė
- Repository master dev
- README
- Treebank hub page
- Download
HSE
5K
- Contributors: Olga Lyashevskaya, Dmitri Sitchinava
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Livvi
1
1K
Uralic, Finnic
Livvi treebanks
KKPP
1K
- Contributors: Tommi A Pirinen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Low Saxon
1
22K
IE, Germanic
Low Saxon treebanks
LSDC
22K
- Contributors: Janine Siewert
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Luxembourgish
1
<1K
IE, Germanic
Luxembourgish treebanks
LuxBank
<1K
- Contributors: Alistair Plum, Christoph Purschke, Caroline Döhmer, Anne-Marie Lutgen, Emilia Milano
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Macedonian
1
1K
IE, Slavic
Macedonian treebanks
MTB
1K
- Contributors: Vladimir Cvetkoski
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Madi
1
<1K
Arawan
Madi treebanks
Jarawara
<1K
- Contributors: Alan Vogel, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Maghrebi Arabic French
1
19K
Code switching
Maghrebi Arabic French treebanks
Arabizi
19K
- Contributors: Arij Riabi, Farah Essaidi, Amal Fethi, Menel Mahamdi, Djamé Seddah
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Makurap
1
<1K
Tupian, Tupari
Makurap treebanks
TuDeT
<1K
- Contributors: Carolina Aragon, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Malayalam
1
2K
Dravidian
Malayalam treebanks
UFAL
2K
- Contributors: Abishek Stephen, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Maltese
1
44K
Afro-Asiatic, Semitic
Maltese treebanks
MUDT
44K
- Contributors: Slavomír Čéplö, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Manchu
1
<1K
Tungusic
Manchu treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Mandyali
1
2K
IE, Indic
Mandyali treebanks
MDTB
2K
- Contributors: Shweta Chauhan, Shefali Saxena, Shweta Jain
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Manx
1
20K
IE, Celtic
Manx treebanks
Cadhan
20K
- Contributors: Kevin Scannell
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Marathi
2
122K
IE, Indic
Marathi treebanks
UFAL
3K
- Contributors: Vinit Ravishankar
- Repository master dev
- README
- Treebank hub page
- Download
CMUPAN
118K
- Contributors: Pranav Kushare, Aditi Chaudhary, Luigi Talamo, Annemarie Verkerk, Helena Vaz
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Mbya Guarani
1
1K
Tupian, Maweti-Guarani
Mbya Guarani treebanks
Thomas
1K
- Contributors: Guillaume Thomas
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Middle Armenian
1
5K
IE, Armenian
Middle Armenian treebanks
ArmTDP
5K
- Contributors: Anna S. Danielyan, Marat M. Yavrumyan
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Middle French
2
164K
IE, Romance
Middle French treebanks
ALTM
7K
- Contributors: Natasha Romanova, Rayan Ziane, Khensa Daoudi, Théo Brillet
- Repository master dev
- README
- Treebank hub page
- Download
PROFITEROLE
156K
- Contributors: Sophie Prévost, Eric Villemonte de la Clergerie, Mathilde Regnault, Loïc Grobol, Benoît Crabbé, Mathieu Dehouck, Alexei Lavrentiev
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Moksha
1
4K
Uralic, Mordvin
Moksha treebanks
JR
4K
- Contributors: Jack Rueter, Maria Levina, Nadezhda Kabaeva, Judit Molnár, Khalid Alnajjar
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Mongolian
1
<1K
Mongolic
Mongolian treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Munduruku
1
1K
Tupian, Munduruku
Munduruku treebanks
TuDeT
1K
- Contributors: Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Naga
1
3K
Sino-Tibetan, Tangkhul-Maring
Naga treebanks
Suansu
3K
- Contributors: Jessica K. Ivani, Kira Tulchynska
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Naija
1
140K
Creole
Naija treebanks
NSC
140K
- Contributors: Bernard Caron, Emmett Strickland, Marine Courtin, Kim Gerdes, Bruno Guillaume, Sylvain Kahane, Chika Kennedy Ajede, Emeka Onwuegbuzia, Samson Tella
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Nanai
1
<1K
Tungusic
Nanai treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Neapolitan
1
<1K
IE, Romance
Neapolitan treebanks
RB
<1K
- Contributors: Rodolfo Basile, Daniel Zeman, Ludovica Pannitto, Arianna Masciolini
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Negidal
1
<1K
Tungusic
Negidal treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Nenets
1
1K
Uralic, Samoyedic
Nenets treebanks
Tundra
1K
- Contributors: Morgane Bona, Bruno Guillaume, Sylvain Kahane, Aleksandra Miletić, Nikolett Mus, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Nepali
1
<1K
IE, Indic
Nepali treebanks
BK
<1K
- Contributors: Samuel BK, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Nheengatu
1
26K
Tupian, Maweti-Guarani
Nheengatu treebanks
CompLin
26K
- Contributors: Leonel Figueiredo de Alencar, Dominick Maia Alexandre
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 North Sami
1
26K
Uralic, Sami
North Sami treebanks
Giella
26K
- Contributors: Trond Trosterud, Lene Antonsen, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Northern Kurdish
1
10K
IE, Iranian
Northern Kurdish treebanks
Kurmanji
10K
- Contributors: Memduh Gökırmak, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Northwest Gbaya
1
4K
Niger-Congo, Gbaya-Manza-Ngbaka
Northwest Gbaya treebanks
Autogramm
4K
- Contributors: Paulette Roulon
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Norwegian
2
611K
IE, Germanic
Norwegian treebanks
Bokmaal
310K
- Contributors: Lilja Øvrelid, Fredrik Jørgensen, Petter Hohle, Thea Tollersrud, Ingerid Løyning Dale, Per Erik Solberg, Andre Kåsen
- Repository master dev
- README
- Treebank hub page
- Download
Nynorsk
301K
- Contributors: Lilja Øvrelid, Fredrik Jørgensen, Petter Hohle, Thea Tollersrud, Ingerid Løyning Dale, Per Erik Solberg, Andre Kåsen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Occitan
1
25K
IE, Romance
Occitan treebanks
TTB
25K
- Contributors: Aleksandra Miletić, Myriam Bras, Louise Esher, Clamença Poujade, Jean Sibille, Marianne Vergez-Couret
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Odia
1
5K
IE, Indic
Odia treebanks
ODTB
5K
- Contributors: Shantipriya Parida, Kalyanamalini Sahoo, Atul Kr. Ojha, Saraswati Sahoo, Biswakalpita Mohapatra, Satya Ranjan Dash, Bijayalaxmi Dash, Kusum Lata
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Old Church Slavonic
1
198K
IE, Slavic
Old Church Slavonic treebanks
PROIEL
198K
- Contributors: Dag Haug
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Old East Slavic
4
581K
IE, Slavic
Old East Slavic treebanks
RNC
168K
- Contributors: Olga Lyashevskaya, Dmitri Sitchinava
- Repository master dev
- README
- Treebank hub page
- Download
Ruthenian
137K
- Contributors: Olga Lyashevskaya, Dmitri Sitchinava, Maria Shvedova
- Repository master dev
- README
- Treebank hub page
- Download
Birchbark
29K
- Contributors: Olga Lyashevskaya
- Repository master dev
- README
- Treebank hub page
- Download
TOROT
246K
- Contributors: Hanne Eckhoff
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Old English
1
<1K
IE, Germanic
Old English treebanks
Cairo
<1K
- Contributors: Lauren Levine, Junghyun Min, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Old French
2
255K
IE, Romance
Old French treebanks
ALTM
15K
- Contributors: Natasha Romanova, Rayan Ziane, Mathieu Goux, Khensa Daoudi, Pierre Larrivée
- Repository master dev
- README
- Treebank hub page
- Download
PROFITEROLE
240K
- Contributors: Sophie Prévost, Aurélie Collomb, Kim Gerdes, Isabelle Tellier, Marine Courtin, Alexei Lavrentiev, Céline Guillot-Barbance, Loïc Grobol, Mathilde Regnault, Mathieu Dehouck
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Old Georgian
3
51K
Kartvelian
Old Georgian treebanks
OGLauRo
11K
- Contributors: Chia-Wei Lin, Diego Luinetti
- Repository master dev
- README
- Treebank hub page
- Download
MidGLauRo
6K
- Contributors: Chia-Wei Lin, Diego Luinetti
- Repository master dev
- README
- Treebank hub page
- Download
GLC
33K
- Contributors: Irina Lobzhanidze
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Old Irish
2
<1K
IE, Celtic
Old Irish treebanks
DipWBG
<1K
- Contributors: Adrian Doyle
- Repository master dev
- README
- Treebank hub page
- Download
DipSGG
<1K
- Contributors: Adrian Doyle
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Old Occitan
2
110K
IE, Romance
Old Occitan treebanks
CronOc
37K
- Contributors: Natasha Romanova, Rayan Ziane
- Repository master dev
- README
- Treebank hub page
- Download
CorAG
72K
- Contributors: Barbara Francioni, Natasha Romanova, Rayan Ziane, Caroline Calvet, Khensa Daoudi, Pierre Larrivée
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Old Turkish
1
<1K
Turkic, Northeastern
Old Turkish treebanks
Clausal
<1K

- Contributors: Mehmet Oguz Derin, Takahiro Harada
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Oroch
1
<1K
Tungusic
Oroch treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Ottoman Turkish
3
34K
Turkic, Southwestern
Ottoman Turkish treebanks
DUDU
25K
- Contributors: Enes Yılandiloğlu
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
<1K
- Contributors: Enes Yılandiloğlu
- Repository master dev
- README
- Treebank hub page
- Download
BOUN
8K
- Contributors: Şaziye Betül Özateş, Tarık Emre Tıraş, Efe Eren Genç, Esma Fatıma Bilgin Taşdemir
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Pali
1
2K
IE, Indic
Pali treebanks
PaliCanon
2K
- Contributors: Chia-Wei Lin, Jasvinder Singh, Khemarato Bhikkhu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Pashto
2
8K
IE, Iranian
Pashto treebanks
Sikaram
6K
- Contributors: Ján Faryad, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Prince
1K
- Contributors: Salwan Aziz, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Paumari
1
<1K
Arawan
Paumari treebanks
TueCL
<1K
- Contributors: Annika Ott, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Peripheral Mongolian
1
<1K
Mongolic
Peripheral Mongolian treebanks
Ordos
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Persian
2
654K
IE, Iranian
Persian treebanks
PerDT
501K
- Contributors: Mohammad Sadegh Rasooli, Pegah Safari, Amirsaeid Moloodi, Alireza Nourian
- Repository master dev
- README
- Treebank hub page
- Download
Seraji
152K
- Contributors: Mojgan Seraji, Filip Ginter, Joakim Nivre, Martin Popel, Daniel Zeman, Minoo Nassajian
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Pesh
1
4K
Chibchan, Pesh
Pesh treebanks
ChibErgIS
4K
- Contributors: Natalia Cáceres Arandia, Claudine Chamoreau, Sylvain Kahane, Bruno Guillaume
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Phrygian
1
2K
IE, Greek
Phrygian treebanks
KUL
2K
- Contributors: Oggi Peeters
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Polish
4
558K
IE, Slavic
Polish treebanks
PDB
349K
- Contributors: Alina Wróblewska, Daniel Zeman, Jan Mašek, Rudolf Rosa
- Repository master dev
- README
- Treebank hub page
- Download
MPDT
59K
- Contributors: Kamil Tomaszek, Alina Wróblewska, Aleksandra Wieczorek
- Repository master dev
- README
- Treebank hub page
- Download
PUD
18K
- Contributors: Alina Wróblewska
- Repository master dev
- README
- Treebank hub page
- Download
LFG
130K
- Contributors: Agnieszka Patejuk, Adam Przepiórkowski
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Pomak
1
34K
IE, Slavic
Pomak treebanks
Philotis
34K
- Contributors: Ritván Karahóǧa, Vivian Stamou, Stella Markantonatou
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Portuguese
10
1,684K
IE, Romance
Portuguese treebanks
PetroGold
250K
- Contributors: Elvis de Souza, Cláudia Freitas, Aline Silveira, Tatiana Cavalcanti, Maria Clara Castro, Wograine Evelyn
- Repository master dev
- README
- Treebank hub page
- Download
Porttinari
168K
- Contributors: Magali Sanches Duran, Lucelene Lopes, Maria das Graças Volpe Nunes, Thiago Alexandre Salgueiro Pardo
- Repository master dev
- README
- Treebank hub page
- Download
PortJur
101K
- Contributors: Lucelene Lopes, Maria das Graças Volpe Nunes, Magali Sanches Duran, Thiago Alexandre Salgueiro Pardo
- Repository master dev
- README
- Treebank hub page
- Download
DANTEStocks
80K
- Contributors: Ariani Di Felippo, Norton Trevisan Roman, Thiago Alexandre Salgueiro Pardo, Bryan Khelven da Silva Barbosa, Maria das Graças Volpe Nunes
- Repository master dev
- README
- Treebank hub page
- Download
Alienista
20K
- Contributors: M.S. Duran, U.P. Sydio, L. Lopes, T.A.S. Pardo
- Repository master dev
- README
- Treebank hub page
- Download
PPrincipe
16K
- Contributors: M.S. Duran, L. Lopes, M.G.V. Nunes, T.A.S. Pardo
- Repository master dev
- README
- Treebank hub page
- Download
Bosque
227K
- Contributors: Alexandre Rademaker, Cláudia Freitas, Elvis de Souza, Aline Silveira, Tatiana Cavalcanti, Wograine Evelyn, Luisa Rocha, Isabela Soares-Bastos, Eckhard Bick, Fabricio Chalub, Guilherme Paulino-Passos, Livy Real, Valeria de Paiva, Daniel Zeman, Martin Popel, David Mareček, Natalia Silveira, André Martins
- Repository master dev
- README
- Treebank hub page
- Download
CINTIL
475K

- Contributors: Mariana Avelãs, António Branco, Marisa Campos, Catarina Carvalheiro, Rita Carvalho, Sérgio Castro, Francisco Costa, Cláudia Martins, Rita Pereira, Sílvia Pereira, Clara Pinto, Andreia Querido, Joana Ramos, João Silva, Sara Silveira
- Repository master dev
- README
- Treebank hub page
- Download
GSD
318K
- Contributors: Alexandre Rademaker, Ryan McDonald, Joakim Nivre, Daniel Zeman, Fabricio Chalub, Carlos Ramisch, Juan Belieni, Vanessa Berwanger Wille, Rodrigo Pintucci
- Repository master dev
- README
- Treebank hub page
- Download
PUD
23K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Gustavo Mendonça, Larissa Rinaldi, Martin Popel, Daniel Zeman, Valeria de Paiva, Alexandre Rademaker, Elvis de Souza
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Prakrit
1
<1K
IE, Indic
Prakrit treebanks
DIPI
<1K
- Contributors: Aryaman Arora, Adam Farris
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Punjabi
3
8K
IE, Indic
Punjabi treebanks
DYZ
4K
- Contributors: Ali Haider Khan, Luigi Talamo, Annemarie Verkerk, Zarina Begum
- Repository master dev
- README
- Treebank hub page
- Download
CS
1K
- Contributors: Ali Haider Khan, Luigi Talamo, Helena Vaz, Zarina Begum, Andrew Thomas Dyer, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Rang
1K
- Contributors: Rimsha Abid, Luigi Talamo, Helena Vaz, Andrew Thomas Dyer, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Romanian
6
942K
IE, Romance
Romanian treebanks
ArT
<1K
- Contributors: Verginica Barbu Mititelu, Mihaela Cristescu, Manuela Nevaci
- Repository master dev
- README
- Treebank hub page
- Download
MolDoRo
<1K
- Contributors: Olesea Caftanatov, Atul Kr. Ojha
- Repository master dev
- README
- Treebank hub page
- Download
Nonstandard
572K
- Contributors: Cătălina Mărănduc, Cenel-Augusto Perez, Victoria Bobicev, Cătălin Mititelu, Florinel Hociung, Valentin Roșca, Roman Untilov, Petru Rebeja
- Repository master dev
- README
- Treebank hub page
- Download
RRT
218K
- Contributors: Verginica Barbu Mititelu, Elena Irimia, Cenel-Augusto Perez, Radu Ion, Radu Simionescu, Martin Popel
- Repository master dev
- README
- Treebank hub page
- Download
SiMoNERo
146K
- Contributors: Maria Mitrofan, Verginica Barbu Mititelu
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
4K
- Contributors: Diana Hoefels, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Russian
5
3,455K
IE, Slavic
Russian treebanks
Taiga
1,758K
- Contributors: Olga Lyashevskaya, Olga Rudina, Natalia Vlasova, Anna Zhuravleva
- Repository master dev
- README
- Treebank hub page
- Download
SynTagRus
1,515K
- Contributors: Kira Droganova, Olga Lyashevskaya, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
GSD
97K
- Contributors: Ryan McDonald, Vitaly Nikolaev, Olga Lyashevskaya
- Repository master dev
- README
- Treebank hub page
- Download
Poetry
64K
- Contributors: Olga Lyashevskaya, Natalia Vlasova, Dmitri Sitchinava
- Repository master dev
- README
- Treebank hub page
- Download
PUD
19K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Tatiana Lando, Olga Loginova, Martin Popel, Daniel Zeman, Kira Droganova
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ruuli
1
8K
Niger-Congo, Bantoid
Ruuli treebanks
RDT
8K
- Contributors: Kira Tulchynska, Anna Veselovsky, Alena Witzlack-Makarevich
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Sanskrit
2
208K
IE, Indic
Sanskrit treebanks
UFAL
1K
- Contributors: Puneet Dwivedi, Daniel Zeman, Erica Biagetti
- Repository master dev
- README
- Treebank hub page
- Download
Vedic
206K
- Contributors: Salvatore Scarlata, Elia Ackermann, Oliver Hellwig, Erica Biagetti, Paul Widmer, Sven Sellmer
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Sardinian
1
7K
IE, Romance
Sardinian treebanks
ContSar
7K
- Contributors: Luigi Talamo, Nicoletta Puddu, Manuela Sanguinetti
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Scottish Gaelic
1
90K
IE, Celtic
Scottish Gaelic treebanks
ARCOSG
90K
- Contributors: Colin Batchelor
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Serbian
2
143K
IE, Slavic
Serbian treebanks
SET
97K
- Contributors: Tanja Samardžić, Aleksandra Miletić, Nikola Ljubešić
- Repository master dev
- README
- Treebank hub page
- Download
ParCoLab
45K
- Contributors: Aleksandra Miletić
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Shanghainese
1
8K
Sino-Tibetan, Chinese
Shanghainese treebanks
ShUD
8K
- Contributors: Qizhen Yang
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Sicilian
1
11K
IE, Romance
Sicilian treebanks
STB
11K
- Contributors: Cristina Bosco, Sabrina D'Alì, Elisa Di Nuovo, Mario Guglielmetti, Caterina Maria Cappello
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Sindhi
1
95K
IE, Indic
Sindhi treebanks
Isra
95K
- Contributors: Mutee-u Rahman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Sinhala
2
1K
IE, Indic
Sinhala treebanks
STB
<1K
- Contributors: Liyanage Chamila, Sarveswaran Kengatharaiyer
- Repository master dev
- README
- Treebank hub page
- Download
Appuwa
<1K
- Contributors: Warangana Sammani, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Skolt Sami
1
3K
Uralic, Sami
Skolt Sami treebanks
Giellagas
3K
- Contributors: Jack Rueter, Markus Juutinen, Francis Tyers, Tommi A Pirinen, Mika Hämäläinen
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Slovak
1
106K
IE, Slavic
Slovak treebanks
SNK
106K
- Contributors: Katarína Gajdošová, Mária Šimková, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Slovenian
2
365K
IE, Slavic
Slovenian treebanks
SSJ
267K
- Contributors: Kaja Dobrovoljc, Tomaž Erjavec, Simon Krek
- Repository master dev
- README
- Treebank hub page
- Download
SST
98K
- Contributors: Kaja Dobrovoljc, Joakim Nivre
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 South Levantine Arabic
1
<1K
Afro-Asiatic, Semitic
South Levantine Arabic treebanks
MADAR
<1K
- Contributors: Shorouq Zahra
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Southern Kurdish
1
1K
IE, Iranian
Southern Kurdish treebanks
Garrusi
1K
- Contributors: Hiwa Asadpour, Luigi Talamo, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Spanish
4
1,023K
IE, Romance
Spanish treebanks
AnCora
560K
- Contributors: Héctor Martínez Alonso, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
PUD
23K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Hector Fernandez Alcalde, Laura Moreno Romero, Martin Popel, Daniel Zeman, Héctor Martínez Alonso
- Repository master dev
- README
- Treebank hub page
- Download
GSD
431K
- Contributors: Miguel Ballesteros, Héctor Martínez Alonso, Ryan McDonald, Elena Pascual, Natalia Silveira, Daniel Zeman, Joakim Nivre, John Bauer
- Repository master dev
- README
- Treebank hub page
- Download
COSER
8K
- Contributors: Johnatan Bonilla
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Spanish Sign Language
1
1K
Sign Language
Spanish Sign Language treebanks
LSE
1K
- Contributors: José María García-Miguel, Carmen Cabeza
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Swedish
6
246K
IE, Germanic
Swedish treebanks
LinES
102K
- Contributors: Lars Ahrenberg
- Repository master dev
- README
- Treebank hub page
- Download
Talbanken
96K
- Contributors: Joakim Nivre, Aaron Smith, Victor Norrman
- Repository master dev
- README
- Treebank hub page
- Download
SweLL
10K
- Contributors: Arianna Masciolini, Aleksandrs Berdicevskis, Maria Irena Szawerna, Caroline Grand-Clement
- Repository master dev
- README
- Treebank hub page
- Download
PUD
19K
- Contributors: Joakim Nivre, Bernadeta Griciūtė, Victor Norrman
- Repository master dev
- README
- Treebank hub page
- Download
Modern
16K
- Contributors: Lars Ahrenberg, Lars Borin, Astrid Ekström, Linus Högberg, Ellinor Lindqvist, Lasse Mårtensson, Joakim Nivre, Eva Pettersson, Yanitsa Stoykova, Sara Stymne
- Repository master dev
- README
- Treebank hub page
- Download
Old
<1K
- Contributors: Lars Ahrenberg, Lars Borin, Astrid Berntsson Ingelstam, Joakim Nivre, Eva Pettersson, Sara Stymne
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Swedish Sign Language
1
1K
Sign Language
Swedish Sign Language treebanks
SSLC
1K
- Contributors: Moa Gärdenfors, Carl Börstell, Robert Östling, Lars Wallin, Mats Wirén
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tagabawa
1
<1K
Austronesian, Greater Central Philippine
Tagabawa treebanks
GJA
<1K
- Contributors: Glyd Aranes
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tagalog
2
1K
Austronesian, Greater Central Philippine
Tagalog treebanks
TRG
<1K
- Contributors: Stephanie Samson, Daniel Zeman, Mary Ann C. Tan
- Repository master dev
- README
- Treebank hub page
- Download
Ugnayan
1K
- Contributors: Angelina Aquino
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tamil
2
12K
Dravidian
Tamil treebanks
MWTT
2K
- Contributors: Sarveswaran Kengatharaiyer, Parameswari Krishnamurthy, Keerthana Balasubramani
- Repository master dev
- README
- Treebank hub page
- Download
TTB
9K
- Contributors: Loganathan Ramasamy, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tangut
1
13K
Sino-Tibetan, Na-Qiangic
Tangut treebanks
MiCA
13K
- Contributors: Wenjie Hua, Chia-Wei Lin, Yuxi Zheng, Yue Ji, Longyu Zhang, Zhengshi Jiang, Amir Zeldes
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Tatar
1
2K
Turkic, Northwestern
Tatar treebanks
NMCTT
2K
- Contributors: Chihiro Taguchi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Teko
1
2K
Tupian, Maweti-Guarani
Teko treebanks
TuDeT
2K
- Contributors: Uliana Vedenina, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Telugu
1
6K
Dravidian
Telugu treebanks
MTG
6K
- Contributors: Taraka Rama, Sowmya Vajjala
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Telugu English
1
<1K
Code switching
Telugu English treebanks
TECT
<1K
- Contributors: Anishka Vissamsetty
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Thai
3
105K
Tai-Kadai
Thai treebanks
TUD
77K
- Contributors: Panyut Sriwirote, Wei Qi Leong, Charin Polpanumas, Santhawat Thanyawong, William Chandra Tjhi, Wirote Aroonmanakun, Attapol T. Rutherford, Ratanon Jiamsundutsadee, Punyanuch Maitreenukul
- Repository master dev
- README
- Treebank hub page
- Download
PUD
22K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Rattima Nitisaroj, Yanin Sawanakunanon, Martin Popel, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
TDT
5K
- Contributors: Siriluck Rattananiyomkul, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Tigrinya
1
1K
Afro-Asiatic, Semitic
Tigrinya treebanks
TiTB
1K
- Contributors: Nazareth Amlesom Kifle, Michael Gasser
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Tswana
1
<1K
Niger-Congo, Bantoid
Tswana treebanks
Popapolelo
<1K
- Contributors: Ansu Berg, Roald Eiselen, Tanja Gaustad, Kevin Mavalela, Rigardt Pretorius
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tu
1
<1K
Mongolic
Tu treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Tupinamba
1
4K
Tupian, Maweti-Guarani
Tupinamba treebanks
TuDeT
4K
- Contributors: Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Turkish
10
735K
Turkic, Southwestern
Turkish treebanks
BOUN
125K
- Contributors: Büşra Marşan, Furkan Akkurt, Utku Türk, Furkan Atmaca, Şaziye Betül Özateş, Gözde Berk, Seyyit Talha Bedir, Abdullatif Köksal, Balkız Öztürk Başaran, Tunga Güngör, Arzucan Özgür
- Repository master dev
- README
- Treebank hub page
- Download
Kenet
178K
- Contributors: Aslı Kuzgun, Neslihan Cesur, Olcay Taner Yıldız, Oğuzhan Kuyrukçu, Arife Betül Yenice, Bilge Nas Arıcan, Ezgi Sanıyar
- Repository master dev
- README
- Treebank hub page
- Download
Penn
183K
- Contributors: Neslihan Cesur, Aslı Kuzgun, Olcay Taner Yıldız, Büşra Marşan, Neslihan Kara, Bilge Nas Arıcan, Merve Özçelik, Deniz Baran Aslan
- Repository master dev
- README
- Treebank hub page
- Download
Tourism
91K
- Contributors: Aslı Kuzgun, Neslihan Cesur, Olcay Taner Yıldız, Oğuzhan Kuyrukçu, Büşra Marşan, Bilge Nas Arıcan, Neslihan Kara, Deniz Baran Aslan, Ezgi Sanıyar, Cengiz Asmazoğlu
- Repository master dev
- README
- Treebank hub page
- Download
Atis
44K
- Contributors: Mehmet Köse, Olcay Taner Yıldız
- Repository master dev
- README
- Treebank hub page
- Download
IMST
58K
- Contributors: Utku Türk, Şaziye Betül Özateş, Büşra Marşan, Furkan Akkurt, Çağrı Çöltekin, Gülşen Cebiroğlu Eryiğit, Memduh Gökırmak, Hüner Kaşıkara, Umut Sulubacak, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
GB
17K
- Contributors: Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
FrameNet
19K
- Contributors: Neslihan Cesur, Aslı Kuzgun, Olcay Taner Yıldız, Büşra Marşan, Oğuzhan Kuyrukçu, Bilge Nas Arıcan, Ezgi Sanıyar, Neslihan Kara, Merve Özçelik
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
<1K
- Contributors: Furkan Akkurt, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
PUD
16K
- Contributors: Hans Uszkoreit, Vivien Macketanz, Aljoscha Burchardt, Kim Harris, Katrin Marheinecke, Slav Petrov, Tolga Kayadelen, Mohammed Attia, Ali Elkahky, Zhuoran Yu, Emily Pitler, Saran Lertpradit, Savas Cetin, Martin Popel, Daniel Zeman, Francis Tyers, Çağrı Çöltekin, Utku Türk, Furkan Atmaca, Şaziye Betül Özateş, Abdullatif Köksal, Balkız Öztürk Başaran, Tunga Güngör, Arzucan Özgür
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Turkish English
1
<1K
Code switching
Turkish English treebanks
BUTR
<1K
- Contributors: Furkan Akkurt, Nursena Teker, Helin Binici, Ahmet Demir, Konstantinos Sampanis
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Turkish German
1
37K
Code switching
Turkish German treebanks
SAGT
37K
- Contributors: Özlem Çetinoğlu, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Udihe
1
<1K
Tungusic
Udihe treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Ukrainian
3
241K
IE, Slavic
Ukrainian treebanks
ParlaMint
109K
- Contributors: Maria Shvedova, Arsenii Lukashevskyi
- Repository master dev
- README
- Treebank hub page
- Download
Zhelekhivka
9K
- Contributors: Maria Shvedova, Arsenii Lukashevskyi
- Repository master dev
- README
- Treebank hub page
- Download
IU
122K
- Contributors: Natalia Kotsyba, Bohdan Moskalevskyi, Mykhailo Romanenko
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Ulch
1
<1K
Tungusic
Ulch treebanks
GDUD
<1K
- Contributors: Wenchao Li, Haitao Liu
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Umbrian
1
1K
IE, Italic
Umbrian treebanks
IKUVINA
1K
- Contributors: Mathieu Dehouck
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Upper Sorbian
1
11K
IE, Slavic
Upper Sorbian treebanks
UFAL
11K
- Contributors: Daniel Zeman, Anna Nedoluzhko
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Urdu
1
138K
IE, Indic
Urdu treebanks
UDTB
138K
- Contributors: Riyaz Ahmad Bhat, Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Uspanteko
1
13K
Mayan
Uspanteko treebanks
MesoTree
13K
- Contributors: Juan Ajsivinac, Robert Henderson, Tomás Méndez López, Cheyenne Wing
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Uyghur
1
40K
Turkic, Southeastern
Uyghur treebanks
UDT
40K
- Contributors: Marhaba Eli, Daniel Zeman, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Uzbek
3
14K
Turkic, Southeastern
Uzbek treebanks
UzUDT
7K
- Contributors: Sanatbek Matlatipov, Elmurod Kuriyozov
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
<1K
- Contributors: Arofat Akhundjanova, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
UT
5K
- Contributors: Arofat Akhundjanova
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Veps
1
1K
Uralic, Finnic
Veps treebanks
VWT
1K
- Contributors: Käbi Laan
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Vietnamese
2
59K
Austro-Asiatic, Viet-Muong
Vietnamese treebanks
VTB
58K
- Contributors: Lương Nguyễn Thị, Linh Hà Mỹ, Phương Lê Hồng, Huyền Nguyễn Thị Minh
- Repository master dev
- README
- Treebank hub page
- Download
TueCL
1K
- Contributors: Hoa Do, Çağrı Çöltekin
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Warlpiri
1
<1K
Pama-Nyungan, Western
Warlpiri treebanks
UFAL
<1K
- Contributors: Daniel Zeman
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Welsh
1
54K
IE, Celtic
Welsh treebanks
CCG
54K
- Contributors: Johannes Heinecke, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Western Armenian
1
122K
IE, Armenian
Western Armenian treebanks
ArmTDP
122K
- Contributors: Marat M. Yavrumyan
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Western S.P. Nahuatl
1
19K
Uto-Aztecan
Western Sierra Puebla Nahuatl treebanks
MesoTree
19K
- Contributors: Robert Pugh, Marivel Huerta Mendez, Mitsuya Sasaki, Francis Tyers, María Ximena Juarez Huerta, Ángeles Márquez Hernández
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Wolof
1
44K
Niger-Congo, Northern Atlantic
Wolof treebanks
WTB
44K
- Contributors: Bamba Dione
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Xavante
1
2K
Macro-Je
Xavante treebanks
XDT
2K
- Contributors: Ivan Roksandic, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Xibe
1
15K
Tungusic
Xibe treebanks
XDT
15K
- Contributors: He Zhou, Juyeon Chung, Elena Klyachko, Francis Tyers, Sandra Kübler
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Yakut
1
1K
Turkic, Northeastern
Yakut treebanks
YKTDT
1K
- Contributors: Tatiana Merzhevich, Fabrício Ferraz Gerardi
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
 Yiddish
1
29K
IE, Germanic
Yiddish treebanks
YiTB
29K
- Contributors: Kirk Andrews
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Yoruba
1
8K
Niger-Congo, Defoid
Yoruba treebanks
YTB
8K
- Contributors: Adédayọ̀ Olúòkun, Daniel Zeman, Seyi Williams, Ọlájídé Ishola
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Yupik
1
1K
Eskimo-Aleut
Yupik treebanks
SLI
1K
- Contributors: Hyunji Hayley Park, Lane Schwartz, Francis Tyers
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Zaar
1
20K
Afro-Asiatic, West Chadic
Zaar treebanks
Autogramm
20K
- Contributors: Sylvain Kahane, Bruno Guillaume, Bernard Caron, Katharine Jiang
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.
Zazaki
1
1K
IE, Iranian
Zazaki treebanks
ZSD
1K
- Contributors: Mahîr Dogan, Luigi Talamo, Helena Vaz, Annemarie Verkerk
- Repository master dev
- README
- Treebank hub page
- Download
Language documentation
See the language documentation page.Disclaimer: Our use of flags to symbolise languages is only intended as a visual enhancement of the website and should not be interpreted as a political statement in any way.
Possible Future Extensions
People have expressed interest in providing annotated data for the following languages but no valid data has been provided so far.
Akkadian
1
117K
Afro-Asiatic, Semitic
Akkadian treebanks
MCONG
117K
Language documentation
See the language documentation page.
Amharic
3
<1K
Afro-Asiatic, Semitic
Amharic treebanks
ADT
<1K
Inku
-
SAMTA
-
Language documentation
See the language documentation page.
Apalai
1
<1K
Cariban
Apalai treebanks
ADT
<1K
Language documentation
The language hub documentation has not yet been created.
Balatipone
1
-
Bororoan
Balatipone treebanks
BDT
-
Language documentation
The language hub documentation has not yet been created.
Balochi
1
-
IE, Iranian
Bengali
3
4K
IE, Indic
Bengali treebanks
CMUPAN
-
PUD
-
Sabdakosh
4K
Language documentation
See the language documentation page.
 Central Romani
1
-
IE, Indic
Central Romani treebanks
Selice
-
Language documentation
The language hub documentation has not yet been created.
 Classical Nahuatl
1
-
Uto-Aztecan
 Corsican
1
-
IE, Romance
Corsican treebanks
DIVITAL
-
Language documentation
The language hub documentation has not yet been created.
Enawene Nawe
1
-
Arawakan, Central Arawakan
Enawene Nawe treebanks
ENDT
-
Language documentation
The language hub documentation has not yet been created.
French
1
-
IE, Romance
French treebanks
ParolesDeNormands
-
Language documentation
See the language documentation page.
Frisian
1
51K
IE, Germanic
Georgian
1
1K
Kartvelian
Georgian treebanks
GEOWIKI
1K
Language documentation
See the language documentation page.
Gilaki
1
-
IE, Iranian
Gilaki treebanks
GileDaar
-
Language documentation
The language hub documentation has not yet been created.
Hiligaynon
1
<1K
Austronesian, Greater Central Philippine
Hiligaynon treebanks
HTB
<1K
Language documentation
The language hub documentation has not yet been created.
Hindi
1
4K
IE, Indic
Hindi treebanks
Convers
4K
Language documentation
See the language documentation page.
Huave
1
16K
Huavean
Italian
1
-
IE, Romance
Italian treebanks
TrIttok
-
Language documentation
See the language documentation page.
Japanese
2
-
Japanese
Japanese treebanks
JDD
-
JDDLUW
-
Language documentation
See the language documentation page.
Kabyle
1
23K
Afro-Asiatic, Berber
Kabyle treebanks
ADPT
23K
Language documentation
The language hub documentation has not yet been created.
Komi
1
<1K
Uralic, Permic
Komi treebanks
OldPermic
<1K
Language documentation
The language hub documentation has not yet been created.
Magahi
2
7K
IE, Indic
Magahi treebanks
MGTB
7K
PUD
-
Language documentation
The language hub documentation has not yet been created.
 Malagasy
1
-
Austronesian, Barito
Malagasy treebanks
Hazo
-
Language documentation
The language hub documentation has not yet been created.
 Mansi
1
-
Uralic, Ugric
Mansi treebanks
CoWS
-
Language documentation
The language hub documentation has not yet been created.
Matigsalug
1
-
Austronesian, Greater Central Philippine
Matigsalug treebanks
GJA
-
Language documentation
The language hub documentation has not yet been created.
Megrelian
1
-
Kartvelian
Megrelian treebanks
MLC
-
Language documentation
See the language documentation page.
Middle Irish
1
3K
IE, Celtic
Middle Persian
1
-
IE, Iranian
Middle Persian treebanks
MPCD
-
Language documentation
See the language documentation page.
Northern Kurdish
1
<1K
IE, Iranian
Northern Kurdish treebanks
Bezeyni
<1K
?
Language documentation
See the language documentation page.
Northern Luri
1
<1K
IE, Iranian
Northern Luri treebanks
Khorramabadi
<1K
Language documentation
See the language documentation page.
Occitan
1
-
IE, Romance
Old English
2
26K
IE, Germanic
Old English treebanks
OEDT
26K
TueCL
-
Language documentation
See the language documentation page.
Old Georgian
1
-
Kartvelian
Old Georgian treebanks
GNC
-
Language documentation
See the language documentation page.
Old Japanese
1
3K
Japanese
Old Occitan
1
-
IE, Romance
Old Occitan treebanks
OOT
-
Language documentation
See the language documentation page.
 Old Saxon
1
1K
IE, Germanic
Palenquero
1
-
Creole
Palenquero treebanks
COL
-
Language documentation
The language hub documentation has not yet been created.
 Papiamento
2
-
Creole
Papiamento treebanks
AW
-
CW
-
Language documentation
The language hub documentation has not yet been created.
Persian
3
-
IE, Iranian
Persian treebanks
HPT
-
IPerUDT
-
PUD
-
Language documentation
See the language documentation page.
Pnar
1
-
Austro-Asiatic, Khasian
Pnar treebanks
PTB
-
Language documentation
The language hub documentation has not yet been created.
Portuguese
1
-
IE, Romance
Portuguese treebanks
DHBB
-
Language documentation
See the language documentation page.
Punjabi
1
6K
IE, Indic
Punjabi treebanks
PunTB
6K
Language documentation
See the language documentation page.
 Puno Quechua
1
-
Quechuan
Puno Quechua treebanks
UIBK
-
Language documentation
The language hub documentation has not yet been created.
Samba Leko
1
-
Niger-Congo, Samba-Duru
Samba Leko treebanks
Autogramm
-
Language documentation
The language hub documentation has not yet been created.
Sardinian
1
-
IE, Romance
Seri
1
-
Hokan, Seri
Sindhi
1
6K
IE, Indic
Spanish
1
<1K
IE, Romance
Spanish treebanks
SVarT
<1K
Language documentation
See the language documentation page.
Spanish English
1
-
Code switching
Spanish English treebanks
Miami
-
Language documentation
The language hub documentation has not yet been created.
 Swahili
1
1K
Niger-Congo, Bantoid
Swahili treebanks
OPUSGV
1K
Language documentation
The language hub documentation has not yet been created.
Swedish
1
-
IE, Germanic
Swedish treebanks
Eukalyptus
-
Language documentation
See the language documentation page.
Tagalog
1
340K
Austronesian, Greater Central Philippine
Tagalog treebanks
NewsCrawl
340K
Language documentation
See the language documentation page.
 Tetun
1
-
Austronesian, Malayo-Polynesian
Tetun treebanks
TUDT
-
Language documentation
The language hub documentation has not yet been created.
 Tunisian Arabic
1
-
Afro-Asiatic, Semitic
Turkish
1
142K
Turkic, Southwestern
Turkish treebanks
ULU
142K
Language documentation
See the language documentation page.
 Turkmen
1
47K
Turkic, Southwestern
Turkmen treebanks
TUD
47K
Language documentation
The language hub documentation has not yet been created.
 Tuwari
1
-
Sepik
Tuwari treebanks
Autogramm
-
Language documentation
The language hub documentation has not yet been created.
Ukrainian
1
-
IE, Slavic
Ukrainian treebanks
PUD
-
Language documentation
See the language documentation page.
Uyghur
1
-
Turkic, Southeastern
Disclaimer: Our use of flags to symbolise languages is only intended as a visual enhancement of the website and should not be interpreted as a political statement in any way.
Retired Treebanks
The following treebanks have been part of one or more UD releases in the past but they are no longer maintained and they have been excluded from the most recent release.
French
1
573K
IE, Romance
French treebanks
FTB
573K
Language documentation
See the language documentation page.
Hindi English
1
26K
Code switching
Hindi English treebanks
HIENCS
26K
Language documentation
The language hub documentation has not yet been created.
Japanese
2
204K
Japanese
Japanese treebanks
Modern
14K
KTC
189K
Language documentation
See the language documentation page.
Khunsari
1
<1K
IE, Iranian
Mbya Guarani
1
11K
Tupian, Maweti-Guarani
Mbya Guarani treebanks
Dooley
11K
Language documentation
See the language documentation page.
Nayini
1
<1K
IE, Iranian
Norwegian
1
55K
IE, Germanic
Norwegian treebanks
NynorskLIA
55K
Language documentation
See the language documentation page.
Soi
1
<1K
IE, Iranian
Disclaimer: Our use of flags to symbolise languages is only intended as a visual enhancement of the website and should not be interpreted as a political statement in any way.
Diversity of the Latest Release
Languages per Family (Genus)
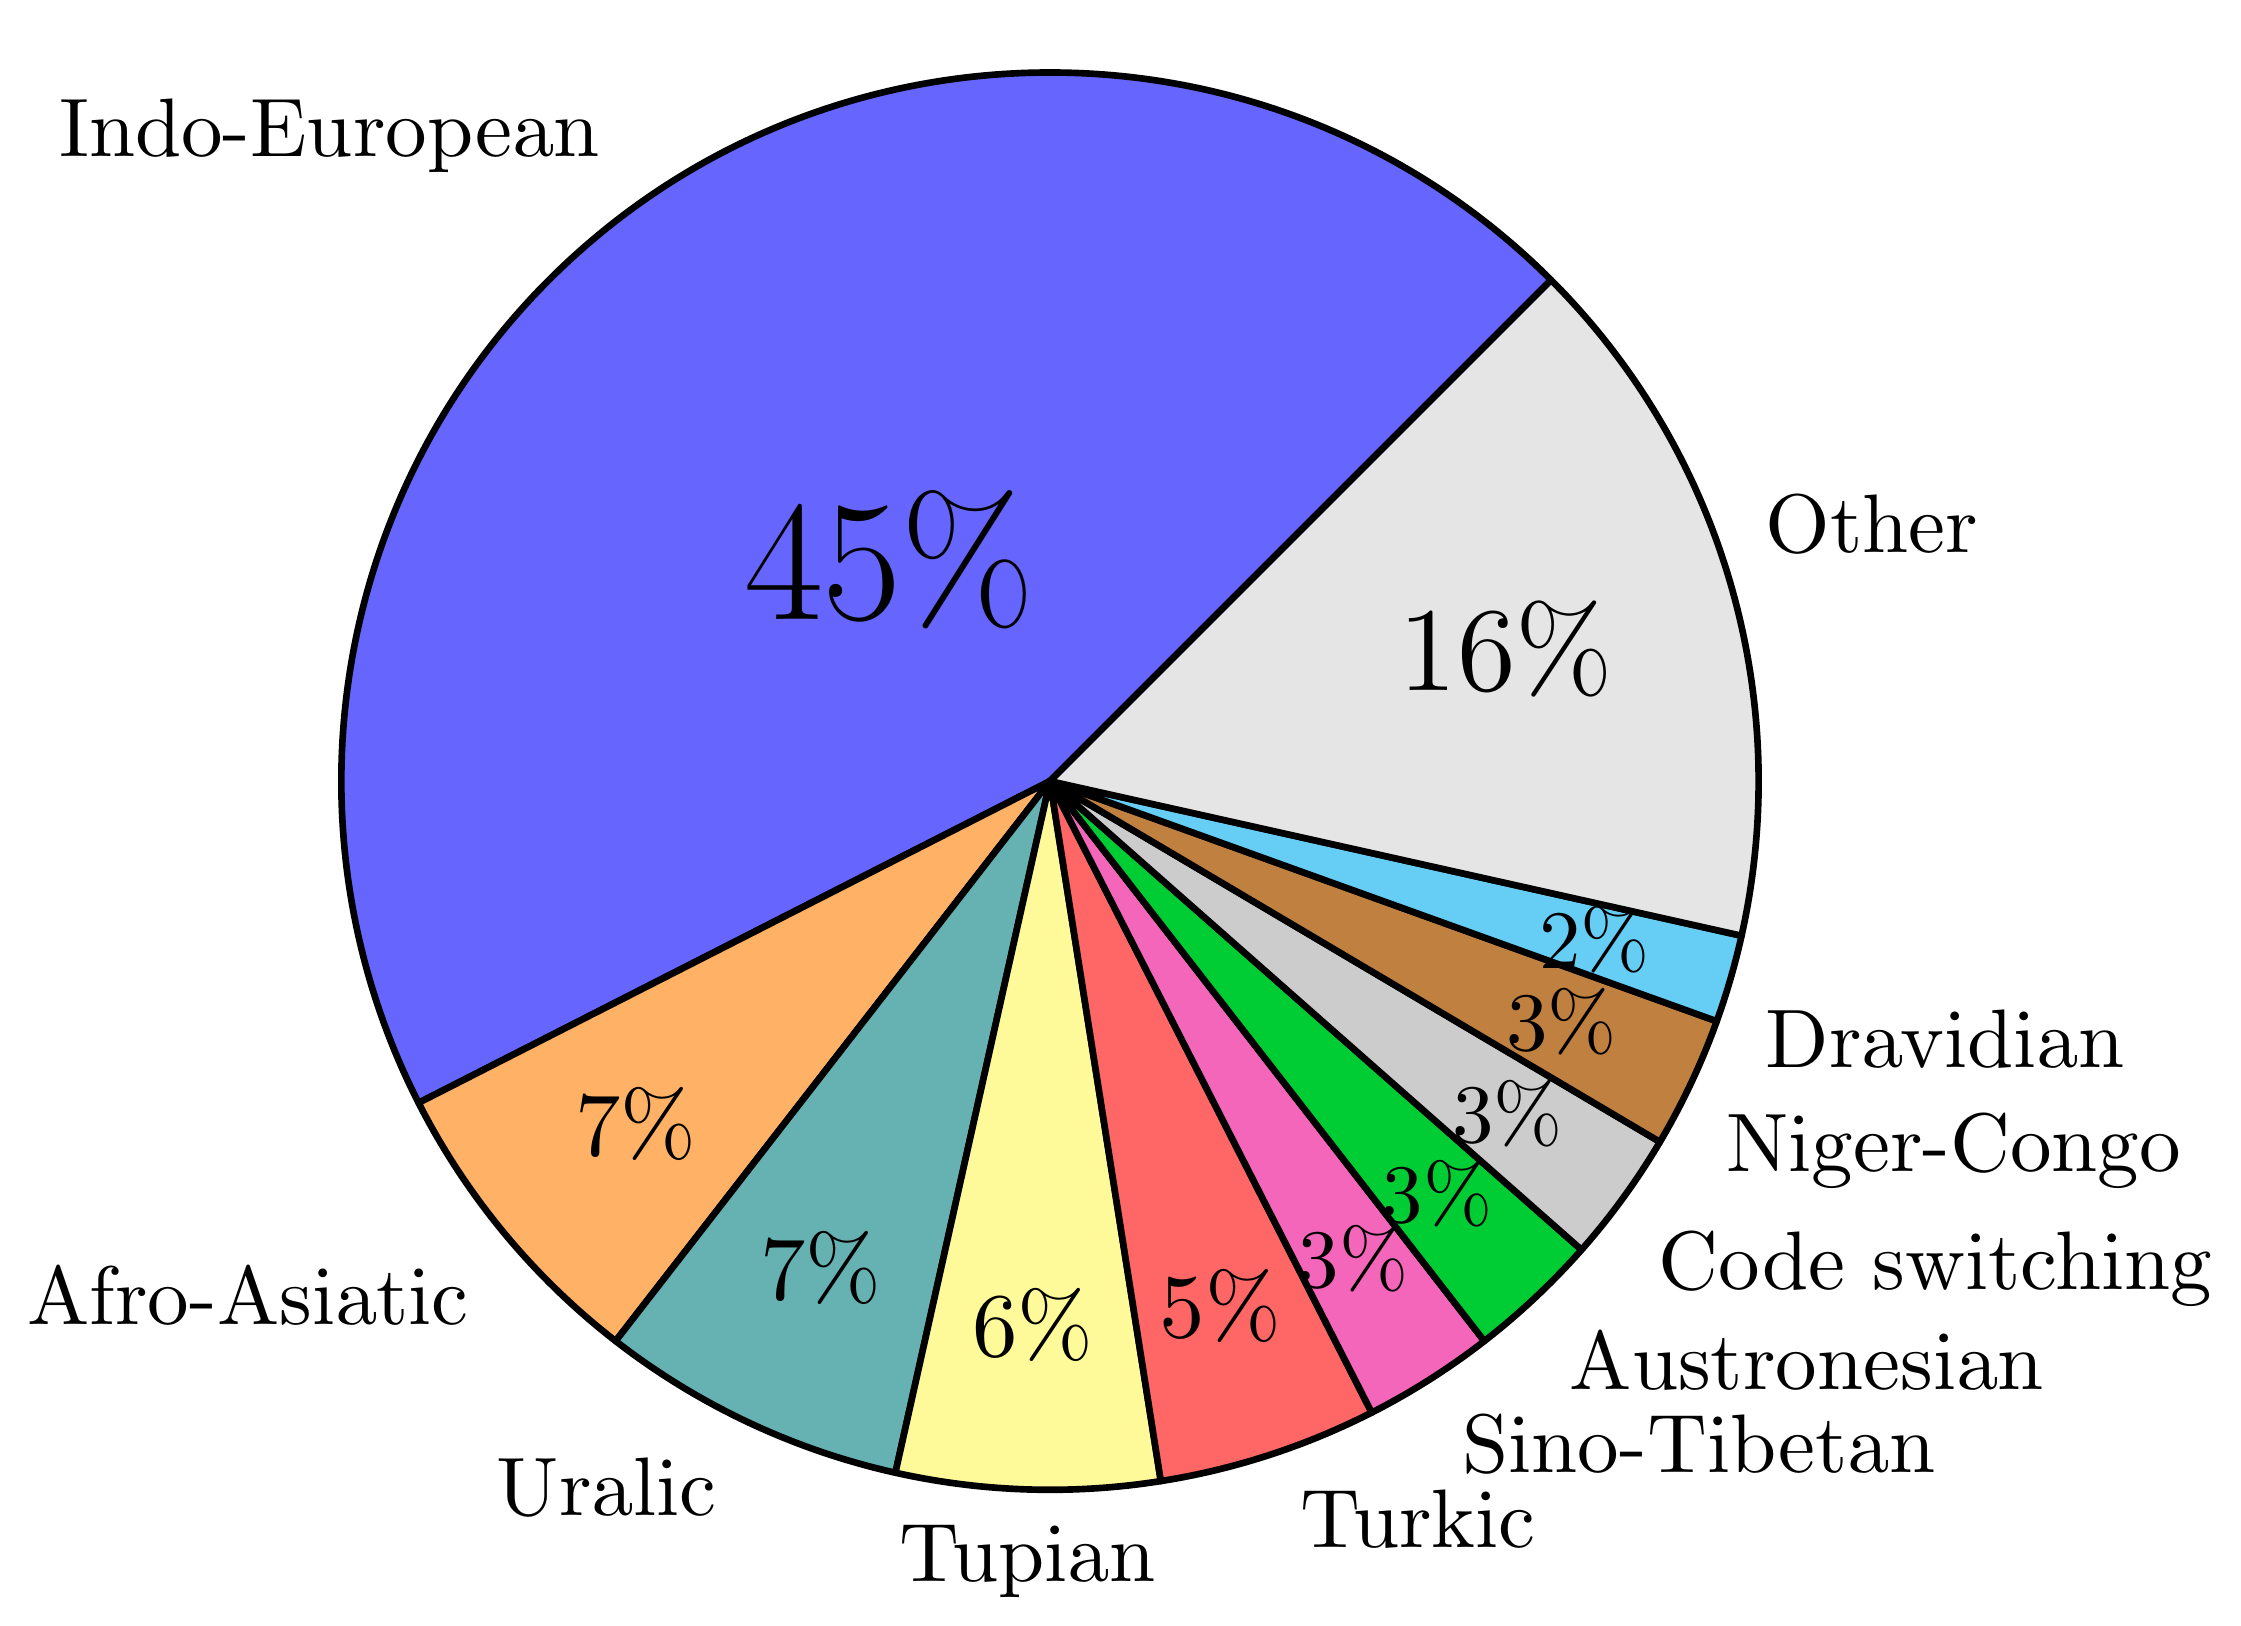
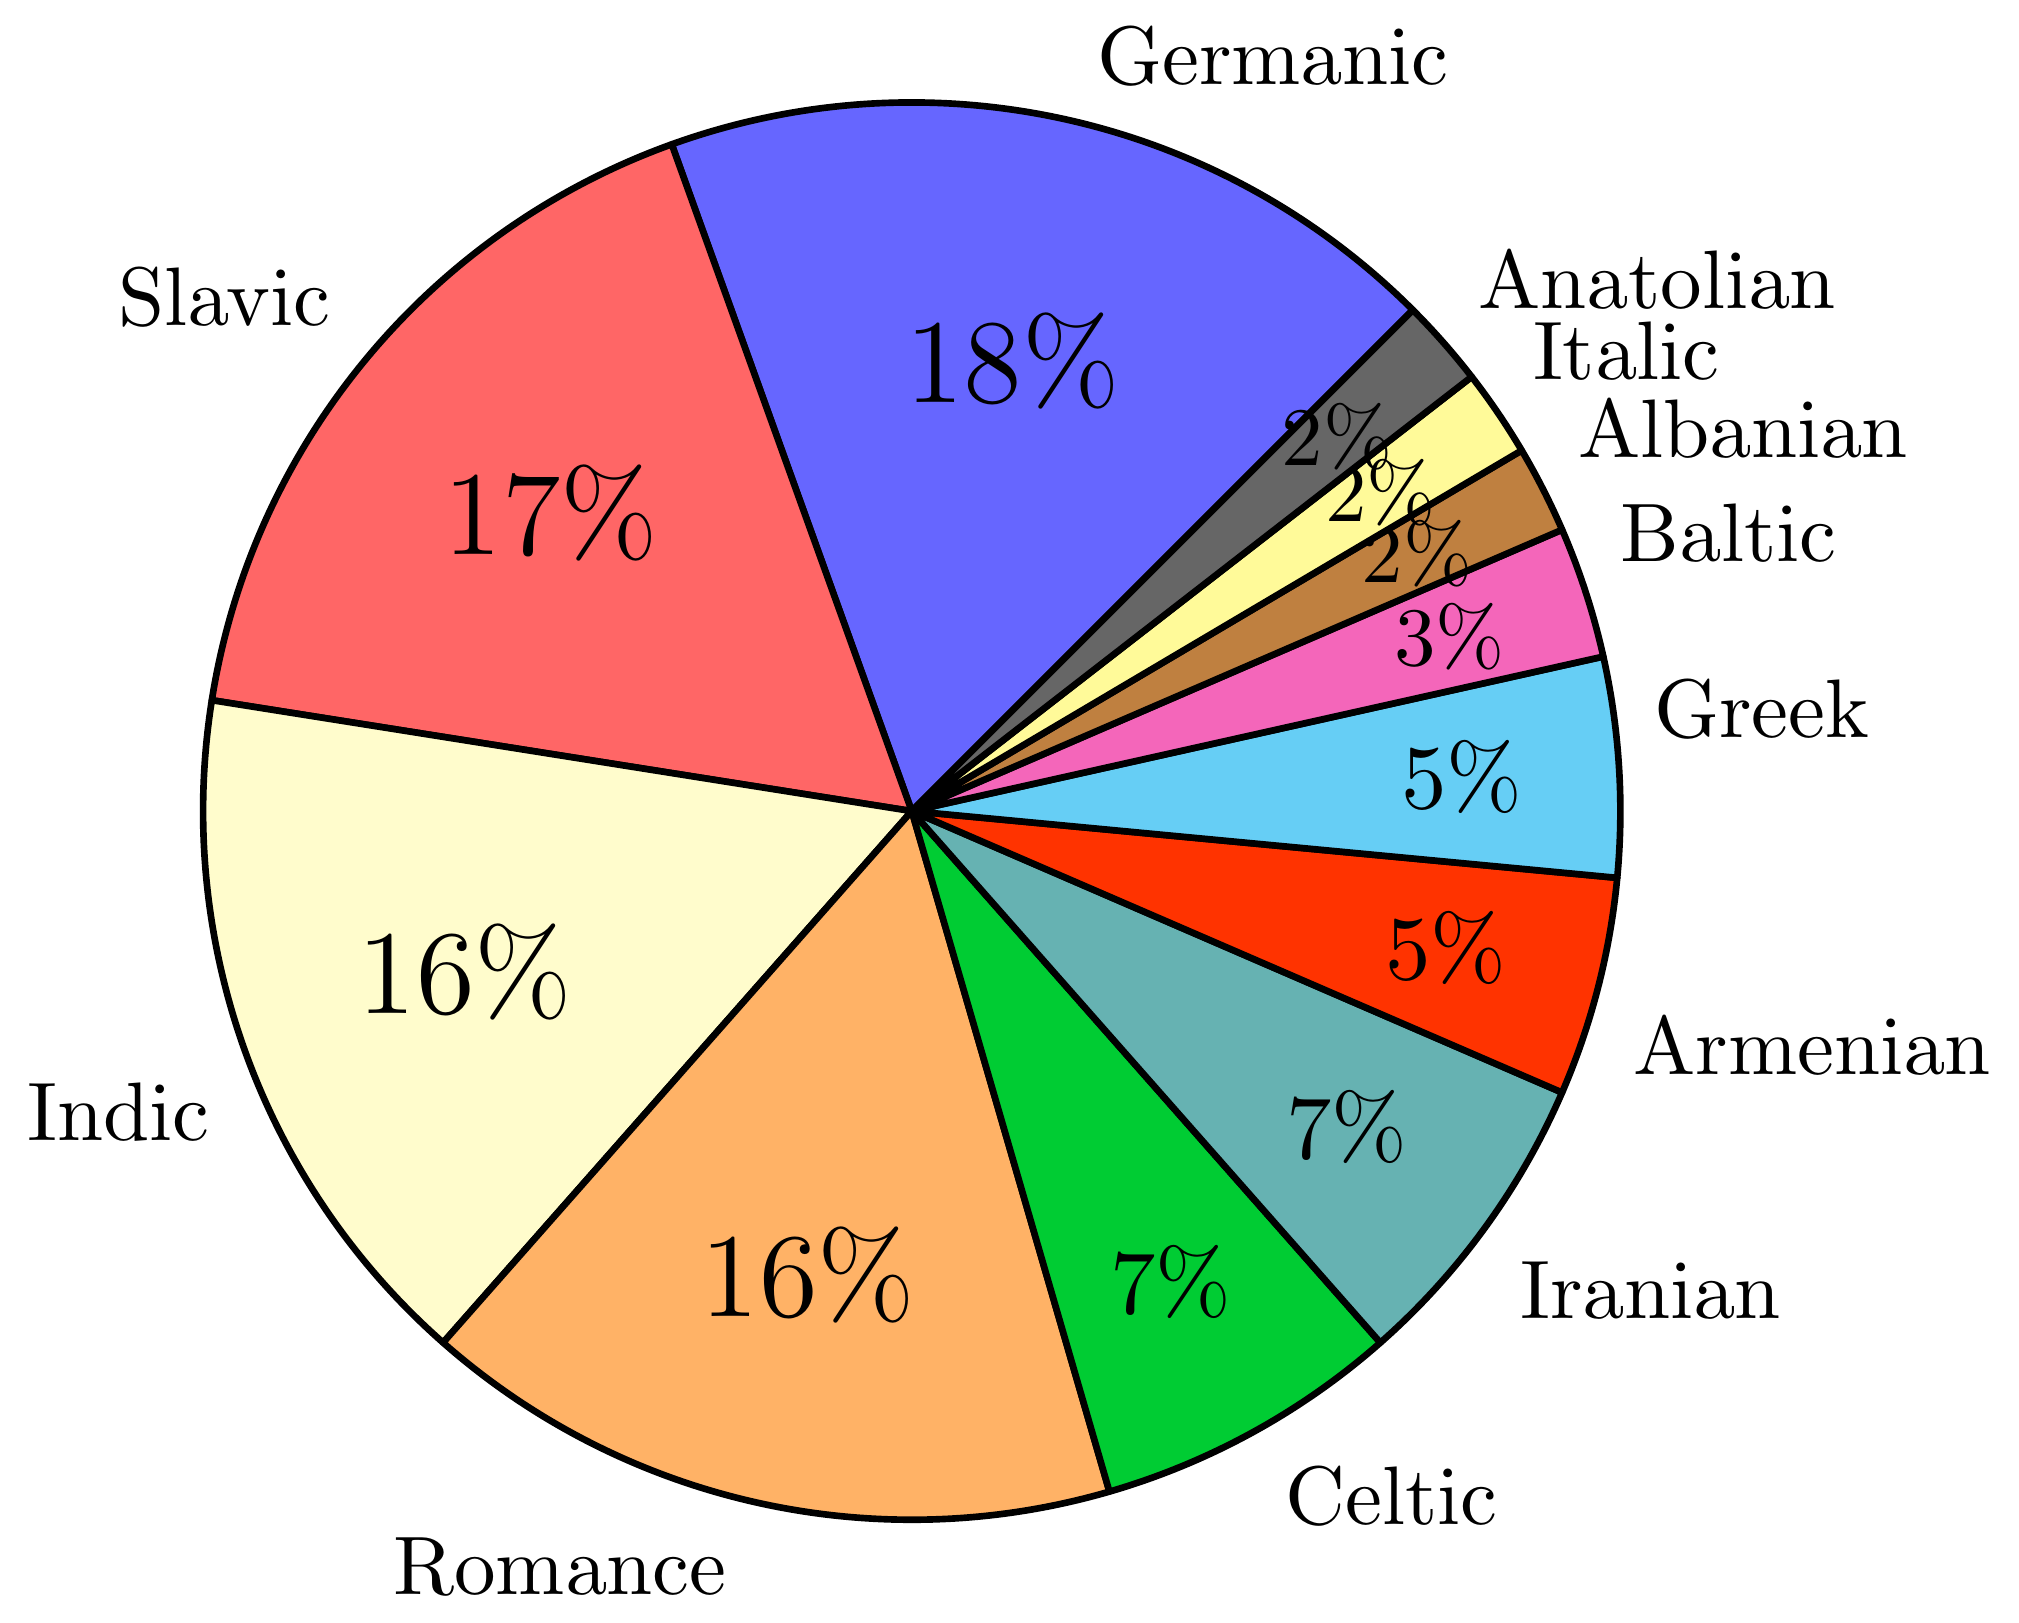
Words per Family (Genus)
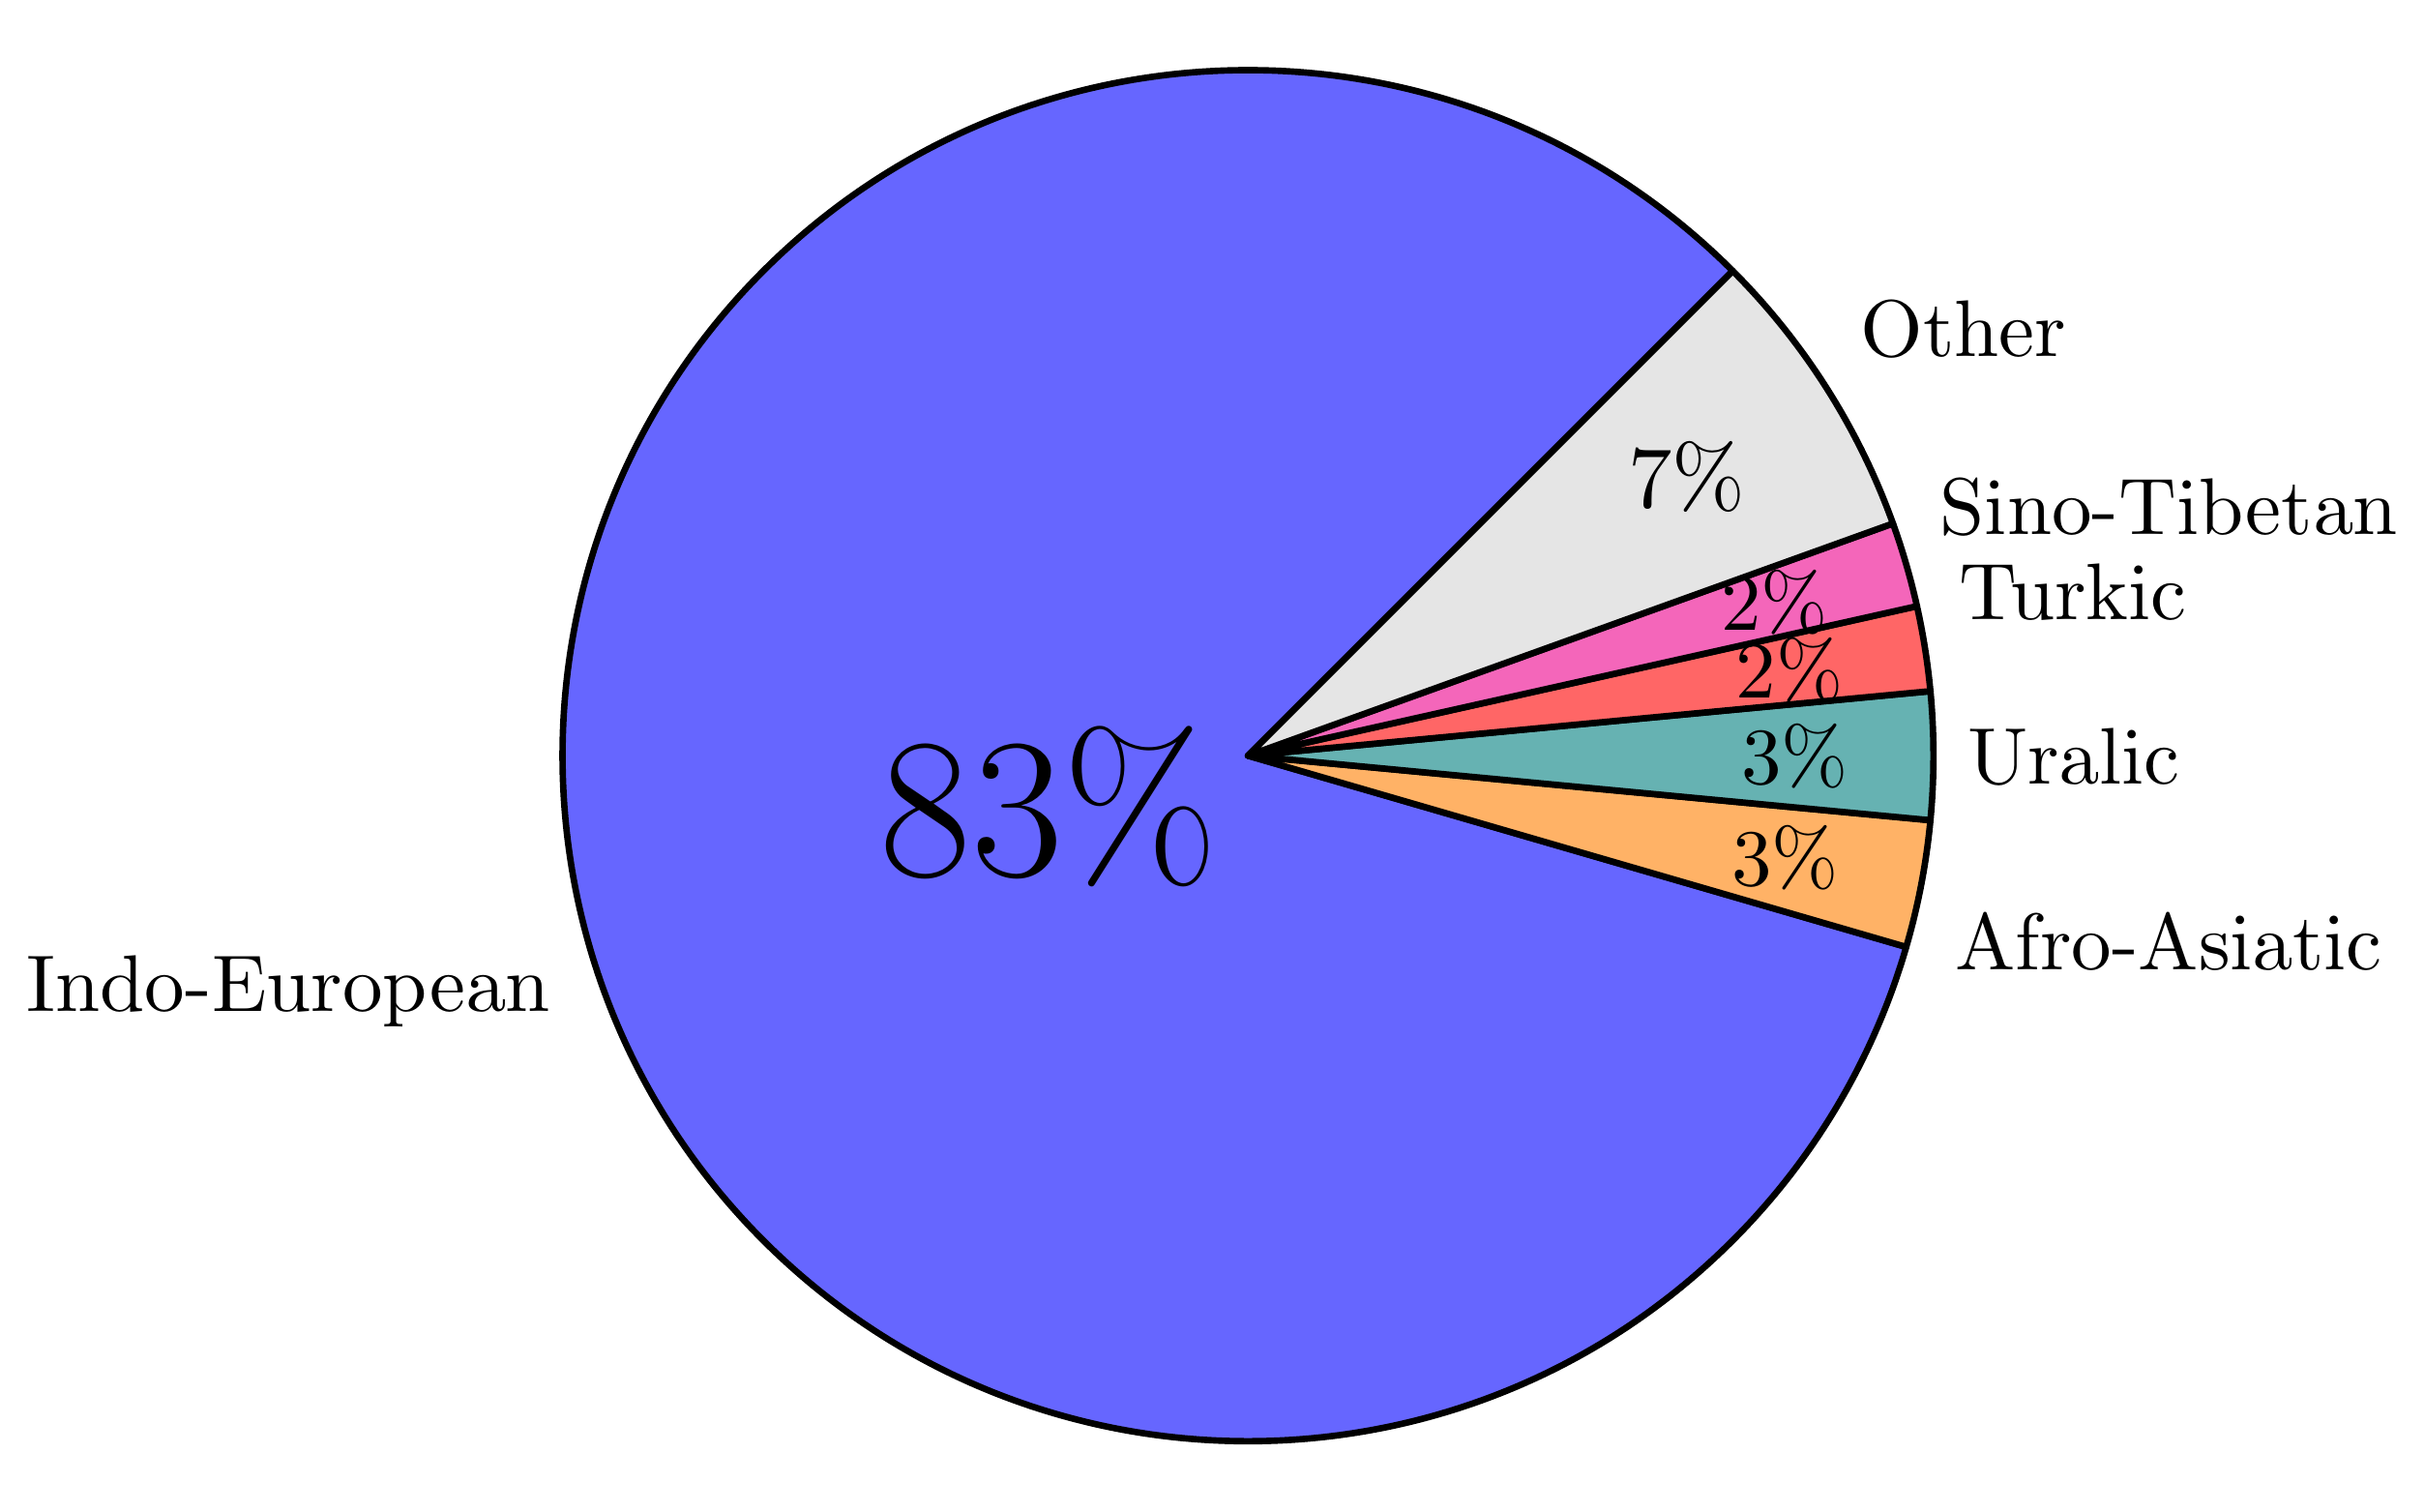
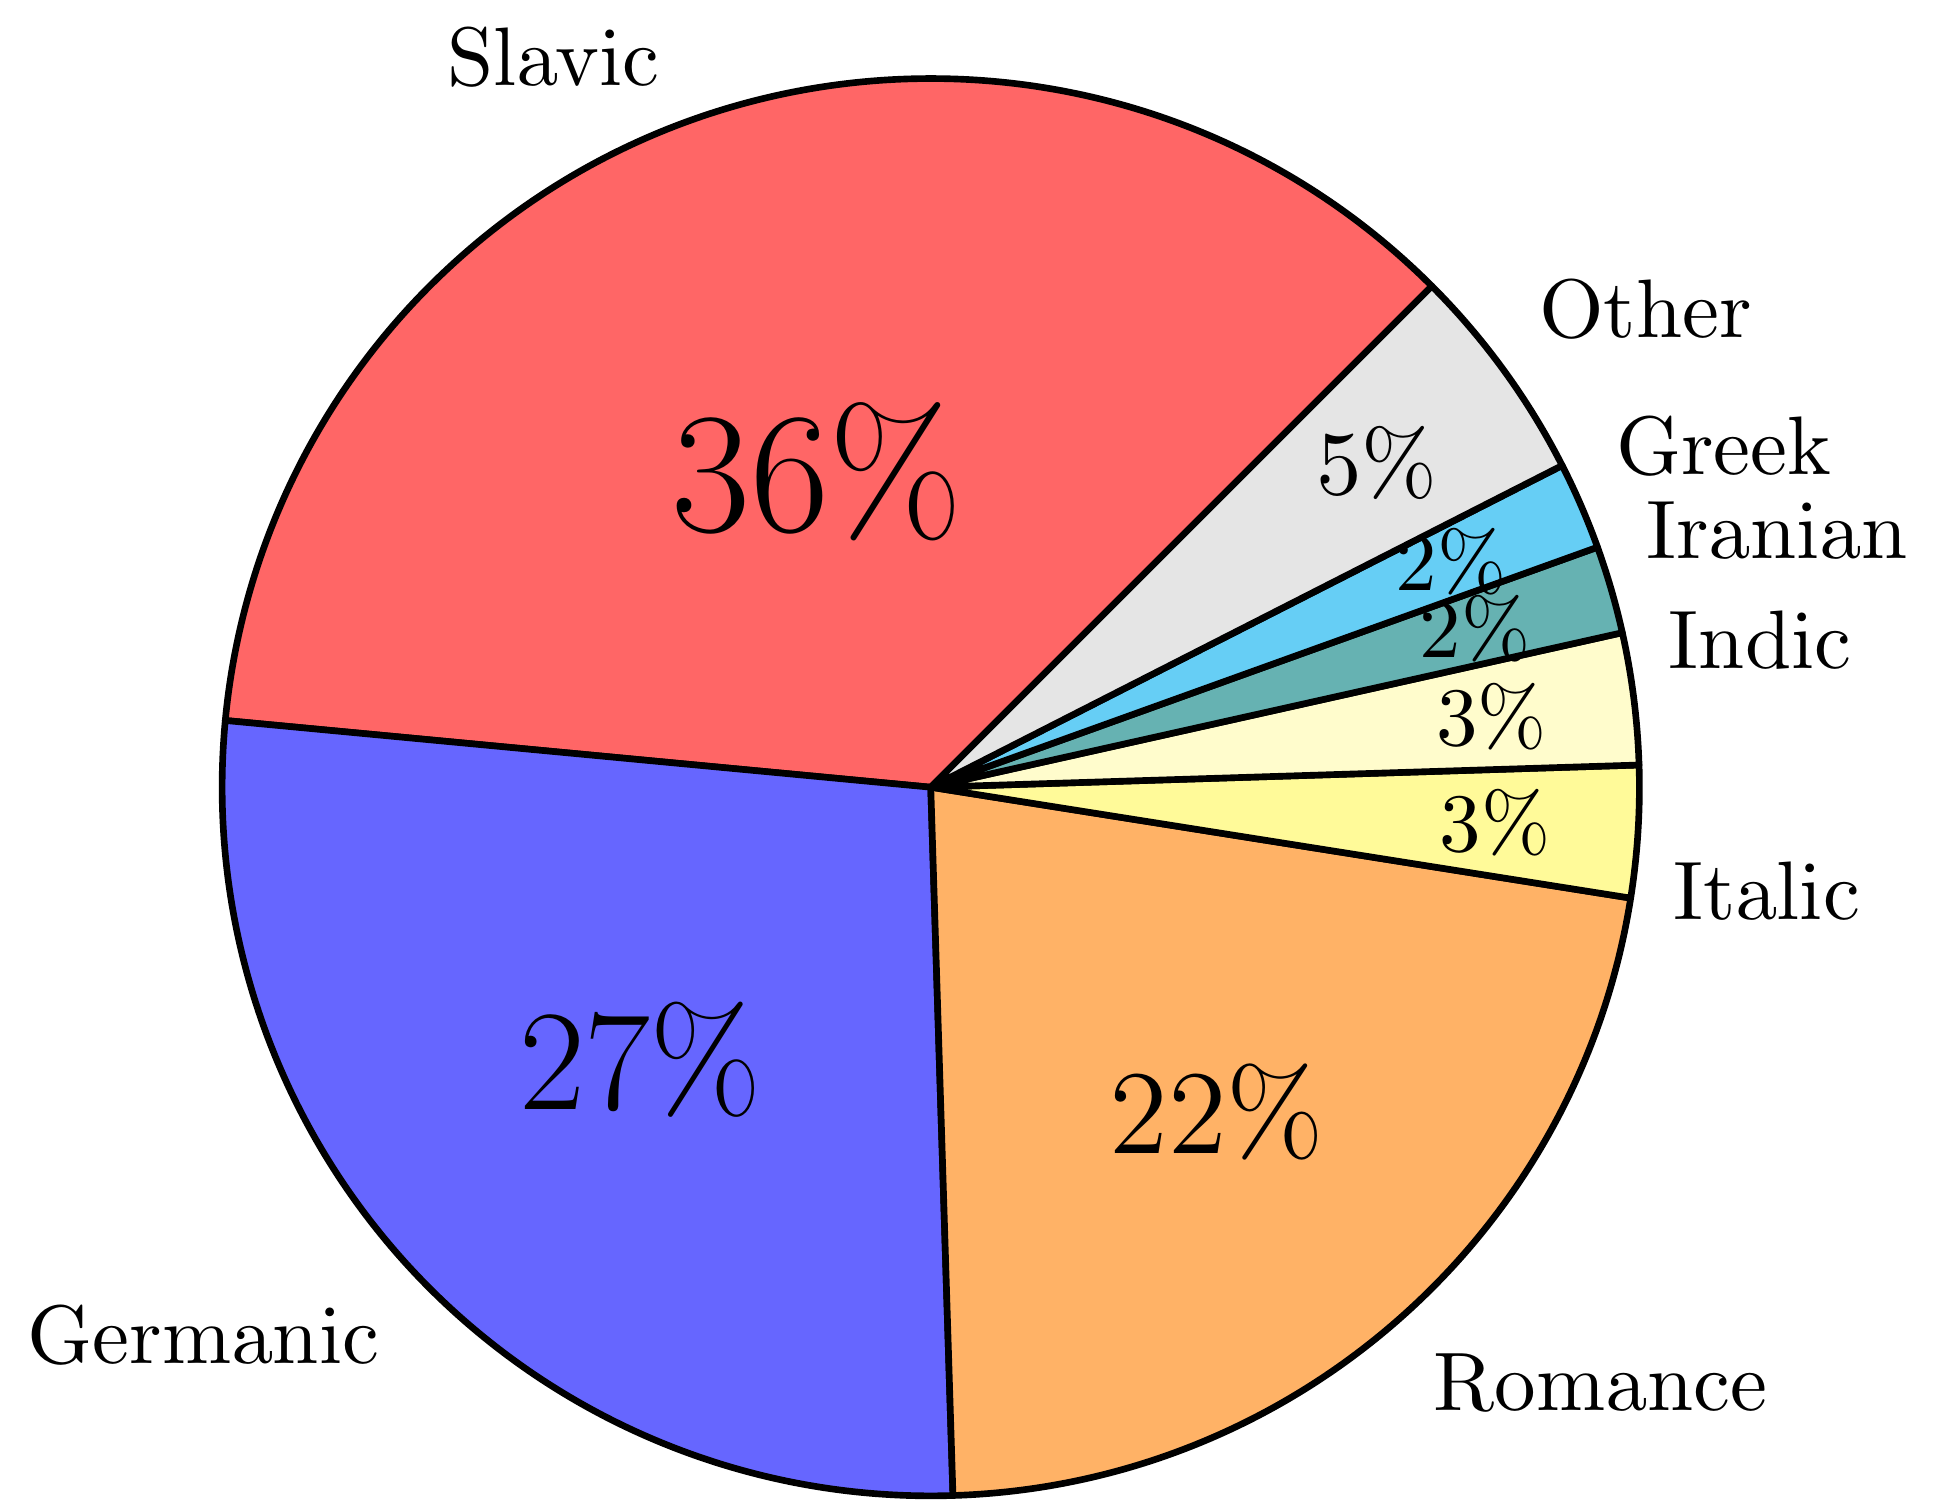
See also separate pages with a list of UD languages and a list of scripts used in UD treebanks.